The Hallucination Alibi: Machine Error as a Deception Channel

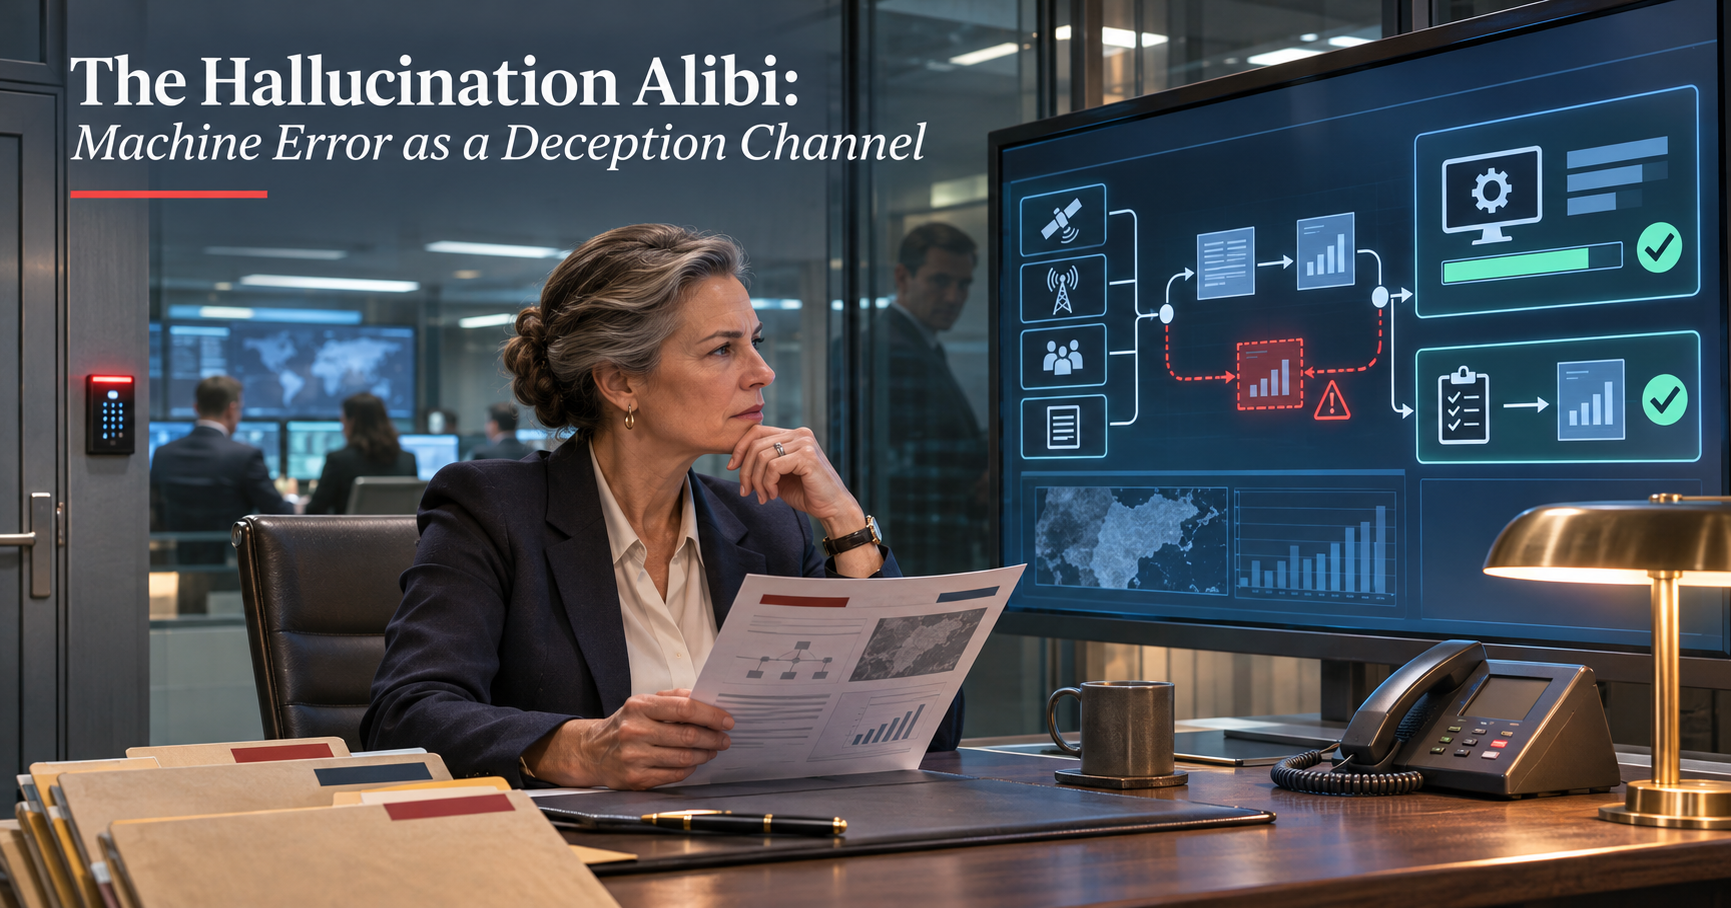
An intelligence analyst sits at her desk holding a printed report and studies a wall monitor showing an automated analysis pipeline, where one step is flagged in red with a warning symbol while the final outputs carry green check marks. A colleague watches from behind a glass wall, with an operations center in the background.

The Machine Lied. Or Did It?

In September 2026, CNN reported that a U.S. military analyst handed intelligence about a Chinese merchant ship’s cargo manifest to an A.I. chatbot, and the chatbot decided the vessel was hauling components for a nuclear weapons program (Maritime Executive 2026). The conclusion went out in a report formatted like every other report, which is to say it wore the uniform. Armed personnel were preparing to board and aircraft were already airborne when officials took a closer look, found the machine behind the curtain, and called the whole thing off (TRT World 2026). One of CNN’s sources said the report “almost started a war” (TRT World 2026).

Goswami (2026) draws the respectable lesson from the episode. Language models flatter the assumptions of the people who use them, they favor digital inputs over human sources, and human judgment therefore remains indispensable. All true. All insufficient. His analysis treats hallucination as a reliability defect, a quality control problem to be managed by putting a competent adult back in the room.

A counterintelligence officer reads the same story and sees something else entirely: a cover story, gift wrapped. The moment a service admits that its machines sometimes invent things, it has published an explanation that the service will reach for on its own, without prompting, every time a machine assessment proves inconvenient. Hallucination is no longer merely an error. It is an alibi, and alibis can be manufactured.

This essay argues that A.I. hallucination opens a deception channel with two distinct operations. In the first, the adversary persuades the defending service that a correct machine assessment is a hallucination. In the second, the adversary makes the defending service’s model hallucinate in fact. Both can be run to increase ambiguity or to mislead, and each feeds the other. The target is no longer the fact. The target is the defender’s confidence in its own analytic machinery, and that is a far softer target than anyone selling A.I. to the intelligence community would like to discuss.

Old Doctrine, New Victim

None of this requires new theory. Daniel and Herbig (1982) gave the field its working taxonomy four decades ago. Ambiguity increasing deception, the A type, buries the target in plausible alternatives until it cannot commit to any of them. Misleading deception, the M type, does the opposite: it reduces ambiguity by building up the attractiveness of one wrong answer until the target embraces it with conviction. The first produces paralysis. The second produces confident error, which is worse, because confident error marches.

Whaley (1969, 1982) established that deception is assembled from two motions, hiding the real and showing the false, and that it succeeds far more often than its victims care to admit. Heuer (1981) supplied the cognitive mechanism. Deceivers rarely need to change what a target believes. They need only feed what the target already believes, because analysts assimilate new information to existing expectations and discount whatever does not fit. Handel (1982) added the corollary that should be tattooed on every analyst’s forearm: the deceiver’s best ally is the victim’s own preconception.

The canonical cases are familiar. Fortitude sold the German high command a landing at the Pas de Calais it already expected (Holt 2004). Barbarossa succeeded in part because Stalin had been led to expect an ultimatum before any attack, and so he read every warning as provocation or noise (Whaley 1973). Wohlstetter (1962) showed at Pearl Harbor that true signals do not announce themselves. They arrive buried in noise, and an adversary who can add noise need not suppress the signal at all.

Hold those three ideas together: reinforce the preconception, discredit the channel, raise the noise. Now observe that the defending services have just installed, at the center of their analytic process, a machine with a publicly documented tendency to fabricate. The doctrine did not change. The victim simply became easier to work.

The Admission Against Interest

Lawyers call a statement that damages the speaker’s own position an admission against interest, and courts trust it precisely because nobody volunteers such things lightly. The A.I. industry and its government customers have made one. Hallucination is not a bug awaiting a patch. The technical literature treats it as a standing property of generative models (Ji et al. 2023), and Xu, Jain, and Kankanhalli (2024) argue formally that it cannot be eliminated from large language models at all.

Add the second documented defect. Models tend to tell users what users want to hear, a behavior the literature politely calls sycophancy (Sharma et al. 2023). Goswami (2026) is right that this corrodes red teaming. He stops short of the operational implication. A machine that confirms the analyst’s prior is Heuer’s reinforcement mechanism, automated, tireless, and available on every desktop. The adversary no longer has to build the comfortable story. The defender’s own tool will write it and format it nicely.

So the defending service now holds two beliefs at once. The machine is useful enough to sit in the analytic line, and the machine sometimes makes things up. That pair of beliefs is the vulnerability. Chesney and Citron (2019) identified its civilian cousin as the liar’s dividend: once the public knows that convincing fakes exist, a liar can wave away authentic evidence as fabricated. Call the intelligence version the hallucination dividend. Once a service knows its models fabricate, any true machine finding can be waved away as fabrication, and the service will do the waving itself.

An adversary did not have to steal this knowledge. It was on CNN.

The First Operation: Discrediting the Truth

The first operation attacks a correct assessment. The machine got it right, and the adversary’s task is to make the defender believe otherwise. The deceiver fabricates nothing about the world. He fabricates doubt about the instrument.

In its ambiguity increasing form, the operation is diffuse. The adversary seeds enough apparent inconsistency around machine generated assessments that every one of them is second guessed, reviewed, and reviewed again. No particular finding is targeted. The objective is tempo. A service that must relitigate each machine output before acting has surrendered the only advantage the machine offered, and the adversary has achieved through friction what he could not achieve through concealment.

In its misleading form, the operation is surgical. The adversary wants one specific true finding rejected, so he engineers the discrepancies that verification will discover. The reviewers go looking for evidence that the machine erred, they find what was left for them, and they kill the assessment with the satisfaction of professionals who have caught a fraud. They are correct that something was fabricated. They are wrong about what.

Read the vessel episode with that lens, strictly as a hypothetical. The public record does not say what the ship carried or where it was bound (TRT World 2026). Nothing reported suggests adversary manipulation, and I do not assert any. But consider what an adversary moving real contraband would want in that exact situation: a machine generated warning, a second look, discovered discrepancies, an aborted boarding, and a chastened service that will hesitate longer the next time. That is the reported outcome. An operation that produced it deliberately would be indistinguishable, from the inside, from the honest catch it resembled. That indistinguishability is the entire problem.

The historical precedent is not a deception at all. It is a self inflicted wound. James Angleton became so convinced that Soviet deception had penetrated the Central Intelligence Agency that he discredited genuine defectors, froze productive operations against the Soviet target, and wrecked careers on suspicion alone (Mangold 1991; Robarge 2003). Whether Moscow engineered that paralysis or merely enjoyed it remains argued. The lesson does not depend on the answer. A service that loses faith in its own channels does the adversary’s work for free, and the first operation aims to induce that condition in the service’s relationship with its machines.

The Second Operation: Manufacturing the Lie

The second operation makes the machine wrong in fact. Here the open literature is uncomfortably generous, and the following stays at the level of doctrine because the peer reviewed record already says more than enough.

The National Institute of Standards and Technology catalogs the attack classes in its adversarial machine learning taxonomy: poisoning of training data, evasion at inference, and direct and indirect prompt injection against generative systems (Vassilev et al. 2025). Each has a deception analogue that any student of Whaley would recognize.

  • Poisoning is the long con. Carlini et al. (2024) demonstrated that corrupting web scale training corpora is practical, not theoretical. Souly et al. (2025) then found that roughly 250 poisoned documents compromised models regardless of model or dataset size. The comforting assumption that sheer volume of clean data dilutes the poison is dead.
  • Corrupting the retrieval layer is the planted document. Zou et al. (2025) reported a 90 percent success rate in steering a model to an attacker chosen answer by injecting five malicious texts into a knowledge base of millions. Every service that points a model at open source material has built a mailbox the adversary can post to.
  • Indirect prompt injection is the forged order. Greshake et al. (2023) showed that instructions hidden in content a model merely reads can redirect what the model does. The analyst never sees the instruction. The machine obeys it anyway.
  • Adversarial inputs are camouflage for sensors. Goodfellow, Shlens, and Szegedy (2015) showed that perturbations invisible to a human can flip a classifier’s judgment. Imagery and signals pipelines that feed an automated assessment inherit that weakness.

The misleading form of this operation steers the model to one specific falsehood, ideally one the defender already suspects. A service at war with a proliferator expects to find proliferation. A model nudged toward “nuclear components” is telling that service a story it has been waiting to hear, with Heuer’s reinforcement and the model’s own sycophancy pulling in the same direction. The ambiguity increasing form is cruder and cheaper: degrade the model unpredictably and let the defender discover that its instrument cannot be trusted.

Note what has changed from classical practice. Fortitude required dummy armies, turned agents, and years of patient radio traffic (Holt 2004). The modern deceiver’s entry cost is a few hundred documents placed where a crawler will find them. Deception has always favored the side with imagination. It now favors the side with imagination and a web host.

The Burn

The two operations are not alternatives. They are a sequence, and the hinge between them is the most dangerous idea in this essay: an induced hallucination that gets caught is not a failed operation.

In classical tradecraft a deception that is detected is blown, and the deceiver pays for it. The machine channel inverts that arithmetic. When the defender catches the model in a fabrication, the defender does not conclude that an adversary is working the channel. The defender concludes that the model hallucinated, because that is what models do and everyone has read the briefing. The adversary’s hand stays hidden behind the model’s reputation. Attribution dies at the alibi.

Meanwhile the catch does real damage. Dietvorst, Simmons, and Massey (2015) documented what they called algorithm aversion: people abandon an algorithm after watching it err, even when it still outperforms the human alternative. One spectacular machine failure, loudly caught, teaches an entire workforce to discount the next machine warning. The adversary who wants a true finding ignored next month can arrange a false finding to be exposed this month. That is the first operation, purchased with the second.

It is the boy who cried wolf, except the adversary is doing the crying and the defender is the one who stops listening. Burn the channel cheaply, then move the real cargo past a service that has learned its lesson. The service will even feel good about it. Skepticism toward the machine will be praised internally as rigor.

The Human in the Loop Is the Loop

Goswami’s (2026) prescription, shared by nearly every commentator on the vessel episode, is the human check. Put an experienced analyst between the machine and the decision. As a quality control measure this is sound. As a security measure it is a sign on the door reading “attack here.”

The human reviewer is squeezed between two documented failure modes. Parasuraman and Manzey (2010) describe automation bias and complacency, the tendency to accept machine output without adequate scrutiny, and they show that it afflicts experts as readily as novices. Dietvorst, Simmons, and Massey (2015) describe the opposite reflex, rejection of the machine after a visible failure. A reviewer is therefore credulous or dismissive depending on recent experience, and recent experience is precisely what an adversary can arrange.

Worse, the reviewer is asking the wrong question. Verification as currently conceived asks whether the machine erred. It does not ask who benefits if the service concludes the machine erred. Those are different inquiries, and only the second is counterintelligence. Jervis (2010) found that intelligence failures typically arise not from stupidity but from plausible inferences that nobody tested against alternatives. “The model hallucinated” is the most plausible inference available in 2026. It is so plausible that it ends the inquiry.

The vessel case also exposed a provenance failure that should alarm anyone who has handled sourced reporting. The chatbot’s conclusion traveled in a product formatted like any other (Maritime Executive 2026). The machine’s contribution was invisible until someone went digging. A human source gets a reliability rating, a reporting history, and a case officer who can be interrogated. The machine got a clean template and a distribution list. No service would tolerate that from a human asset, and yet here we are.

Counterdeception for the Machine Age

Bennett and Waltz (2007) reduce counterdeception to a discipline: know the adversary’s deception practices, know your own vulnerabilities, and test anomalies instead of explaining them away. Applied to the machine channel, that discipline yields six requirements.

  • Treat “hallucination” as a hypothesis, never a finding. When a machine assessment is rejected, the rejection must survive the same analysis of competing hypotheses that Heuer (1999) prescribed for any judgment. Random error, induced error, and correct output discredited by planted discrepancies are three hypotheses. A service that considers only the first has stopped thinking.
  • Run the machine like a source. Every machine derived judgment should carry visible provenance, a reliability history, and a record of what it was shown. If a service would not disseminate an unsourced claim from a walk in, it should not disseminate one from a chatbot in a clean template.
  • Defend the pipeline as a counterintelligence target. Training corpora, retrieval stores, and open source feeds are the model’s access agents. They deserve the vetting, compartmentation, and lineage controls applied to any other access. Goswami (2026) notes that counterintelligence must protect data centers and satellites. It must also protect what the model reads.
  • Audit the verifiers. Each time human review overturns a machine assessment, someone outside that review should ask where the disconfirming evidence came from, how it arrived, and whether its arrival was convenient.
  • Demand independent corroboration before action and before dismissal. A finding confirmed or refuted only by material the adversary could have touched has not been confirmed or refuted. Human sources and collection channels outside the model’s reach remain the only true cross check.
  • Study the error pattern. Honest hallucination should be indifferent to the adversary’s interests. If a model’s errors, or its discredited successes, cluster around one adversary’s equities, that is not noise. That is a signature, and it will only be visible to a service that records every such event centrally instead of burying each one as an embarrassment.

None of this is exotic. It is the tradecraft every competent service already applies to human sources, extended to a new and unusually gullible one.

Conclusion

The commentary on the vessel episode has settled into a comfortable moral: the machine erred, the humans caught it, the system worked. That reading is a lullaby. The system worked against an accident. Nothing in the public record shows that it would work against an adversary who understands that the defender now carries a prepared excuse for every inconvenient machine finding and a prepared distrust waiting to be triggered.

Hallucination gives the deceiver both of Daniel and Herbig’s instruments in one package. He can raise ambiguity by teaching a service to doubt its machines, and he can mislead by teaching the machines to lie. He can do the second in order to achieve the first, and when he is caught, the model takes the blame. No deception planner in history has enjoyed a channel that apologizes on his behalf.

The intelligence services are bolting generative models onto their analytic lines at speed, and the adversaries are reading the same technical literature with considerably more malice. The question for a defending service is not whether its A.I. will hallucinate. It will. The question is whether, when it does, anyone in the building is paid to ask who wanted it to, and whether, when it does not, anyone is paid to notice that the truth was just talked out of the room. Follow my blog for more “truths”.

~ C. Constantin Poindexter, MA in Intelligence, Graduate Certificate in Counterintelligence, JD, CISA/NCISS OSINT certification, DoD/DoS BFFOC Certification, Criminal Intelligence Analyst Classification 1 (IALEIA)

References

  • Bennett, Michael, and Edward Waltz. 2007. Counterdeception Principles and Applications for National Security. Norwood, MA: Artech House.
  • Carlini, Nicholas, Matthew Jagielski, Christopher A. Choquette-Choo, Daniel Paleka, Will Pearce, Hyrum Anderson, Andreas Terzis, Kurt Thomas, and Florian Tramèr. 2024. “Poisoning Web-Scale Training Datasets Is Practical.” In 2024 IEEE Symposium on Security and Privacy. San Francisco: IEEE.
  • Chesney, Robert, and Danielle Keats Citron. 2019. “Deep Fakes: A Looming Challenge for Privacy, Democracy, and National Security.” California Law Review 107 (6): 1753–1820.
  • Daniel, Donald C., and Katherine L. Herbig. 1982. “Propositions on Military Deception.” In Strategic Military Deception, edited by Donald C. Daniel and Katherine L. Herbig, 3–30. New York: Pergamon Press.
  • Dietvorst, Berkeley J., Joseph P. Simmons, and Cade Massey. 2015. “Algorithm Aversion: People Erroneously Avoid Algorithms After Seeing Them Err.” Journal of Experimental Psychology: General 144 (1): 114–26.
  • Goodfellow, Ian J., Jonathon Shlens, and Christian Szegedy. 2015. “Explaining and Harnessing Adversarial Examples.” Paper presented at the International Conference on Learning Representations, San Diego, May 2015. https://arxiv.org/abs/1412.6572.
  • Goswami, Archishman Ray. 2026. “AI and the False Promise of Intelligence Analysis.” Observer Research Foundation, October 12, 2026. https://www.orfonline.org/expert-speak/ai-and-the-false-promise-of-intelligence-analysis.
  • Greshake, Kai, Sahar Abdelnabi, Shailesh Mishra, Christoph Endres, Thorsten Holz, and Mario Fritz. 2023. “Not What You’ve Signed Up For: Compromising Real-World LLM-Integrated Applications with Indirect Prompt Injection.” In Proceedings of the 16th ACM Workshop on Artificial Intelligence and Security, 79–90. New York: ACM.
  • Handel, Michael I. 1982. “Intelligence and Deception.” Journal of Strategic Studies 5 (1): 122–54.
  • Heuer, Richards J., Jr. 1981. “Strategic Deception and Counterdeception: A Cognitive Process Approach.” International Studies Quarterly 25 (2): 294–327.
  • Heuer, Richards J., Jr. 1999. Psychology of Intelligence Analysis. Washington, DC: Center for the Study of Intelligence, Central Intelligence Agency.
  • Holt, Thaddeus. 2004. The Deceivers: Allied Military Deception in the Second World War. New York: Scribner.
  • Jervis, Robert. 2010. Why Intelligence Fails: Lessons from the Iranian Revolution and the Iraq War. Ithaca, NY: Cornell University Press.
  • Ji, Ziwei, Nayeon Lee, Rita Frieske, Tiezheng Yu, Dan Su, Yan Xu, Etsuko Ishii, Ye Jin Bang, Andrea Madotto, and Pascale Fung. 2023. “Survey of Hallucination in Natural Language Generation.” ACM Computing Surveys 55 (12): 1–38.
  • Mangold, Tom. 1991. Cold Warrior: James Jesus Angleton, the CIA’s Master Spy Hunter. New York: Simon and Schuster.
  • Maritime Executive. 2026. “Report: AI Mistake Nearly Led U.S. Military to Board a Chinese Ship.” September 2026. https://maritime-executive.com/article/report-ai-mistake-nearly-led-u-s-military-to-board-a-chinese-ship.
  • Parasuraman, Raja, and Dietrich H. Manzey. 2010. “Complacency and Bias in Human Use of Automation: An Attentional Integration.” Human Factors 52 (3): 381–410.
  • Robarge, David. 2003. “Moles, Defectors, and Deceptions: James Angleton and CIA Counterintelligence.” Journal of Intelligence History 3 (2): 21–49.
  • Sharma, Mrinank, Meg Tong, Tomasz Korbak, David Duvenaud, Amanda Askell, Samuel R. Bowman, et al. 2023. “Towards Understanding Sycophancy in Language Models.” Preprint, arXiv. https://arxiv.org/abs/2310.13548.
  • Souly, Alexandra, Javier Rando, Ed Chapman, Xander Davies, Burak Hasircioglu, Ezzeldin Shereen, Carlos Mougan, et al. 2025. “Poisoning Attacks on LLMs Require a Near-Constant Number of Poison Samples.” Preprint, arXiv. https://arxiv.org/abs/2510.07192.
  • TRT World. 2026. “‘Entirely False’ AI-Linked Intel Almost Led US to Raid China Ship.” September 2026. https://www.trtworld.com/article/a125bbf303a3.
  • Vassilev, Apostol, Alina Oprea, Alie Fordyce, Hyrum Anderson, Xander Davies, and Maia Hamin. 2025. Adversarial Machine Learning: A Taxonomy and Terminology of Attacks and Mitigations. NIST AI 100-2e2025. Gaithersburg, MD: National Institute of Standards and Technology. https://doi.org/10.6028/NIST.AI.100-2e2025.
  • Whaley, Barton. 1969. Stratagem: Deception and Surprise in War. Cambridge, MA: Center for International Studies, Massachusetts Institute of Technology.
  • Whaley, Barton. 1973. Codeword BARBAROSSA. Cambridge, MA: MIT Press.
  • Whaley, Barton. 1982. “Toward a General Theory of Deception.” Journal of Strategic Studies 5 (1): 178–92.
  • Wohlstetter, Roberta. 1962. Pearl Harbor: Warning and Decision. Stanford, CA: Stanford University Press.
  • Xu, Ziwei, Sanjay Jain, and Mohan Kankanhalli. 2024. “Hallucination Is Inevitable: An Innate Limitation of Large Language Models.” Preprint, arXiv. https://arxiv.org/abs/2401.11817.
  • Zou, Wei, Runpeng Geng, Binghui Wang, and Jinyuan Jia. 2025. “PoisonedRAG: Knowledge Corruption Attacks to Retrieval-Augmented Generation of Large Language Models.” In Proceedings of the 34th USENIX Security Symposium, 3827–44. Seattle: USENIX Association.
Share this post:

Consorcio de Datos de la Comunidad de Inteligencia: OSINT, Equilibrando la Seguridad Nacional y las Libertades Civiles

OSINT, inteligencia, CNI, contrainteligencia, contraespionaje, espionaje, c. constantin poindexter

La Oficina del Director de Inteligencia Nacional (ODNI, por sus siglas en inglés) ha presentado planes para el Consorcio de Datos de la Comunidad de Inteligencia (ICDC, por sus siglas en inglés), una plataforma centralizada diseñada para agilizar la adquisición de información comercialmente disponible (CAI) por parte de la Comunidad de Inteligencia. Esta iniciativa busca mejorar la accesibilidad y eficiencia de los datos en toda la Comunidad. No obstante, el ICDC ha generado un debate de corte tradicional, similar al que rodea la FISA, respecto a sus implicaciones para los derechos de privacidad de los ciudadanos estadounidenses y el posible deterioro de las protecciones constitucionales.

Comprendiendo la Iniciativa ICDC

El ICDC representa un esfuerzo coordinado por parte de la comunidad de inteligencia estadounidense para modernizar y centralizar la adquisición de CAI. Según los documentos oficiales de licitación, el ICDC se concibe como un “mercado para consultar e interactuar con los archivos de los proveedores”, con énfasis en un objetivo arquitectónico de “cero copias”, lo que significa que los datos se consultarán directamente en los sistemas de los proveedores en lugar de copiarse a servidores gubernamentales. Este enfoque pretende reducir la duplicación de datos y mejorar la eficiencia operativa. La plataforma está diseñada para operar completamente a nivel de computación no clasificada, permaneciendo toda su actividad en ese nivel. Ofrecerá múltiples opciones de interacción con los datos, incluyendo búsqueda a través de interfaces gráficas o web (GUI/WUI), llamadas API, acceso a datos en bloque y opciones de inicio de sesión en portales web externos. Se destaca el uso de código abierto y la adhesión a estándares de la industria como las especificaciones OpenAPI, a fin de garantizar flexibilidad y evitar la dependencia de un único proveedor.

Peligros Potenciales para Ciudadanos Inocentes

Si bien el ICDC tiene como objetivo mejorar las operaciones de inteligencia, plantea serias preocupaciones respecto a la privacidad de ciudadanos inocentes.

La amplitud de la recopilación de datos es problemática. La recolección masiva de información sobre personas completamente libres de sospecha o interés por parte de la Comunidad de Inteligencia es el proverbial elefante en la habitación. El ICDC facilita el acceso a cantidades inmensas de datos personales, incluidos registros de ubicación, información biométrica y actividades en línea, sin la necesidad de autorizaciones legales tradicionales, como las otorgadas por el Tribunal FISA. Esta recolección expansiva probablemente incluirá información sobre personas que no se encuentran bajo ninguna sospecha, constituyendo una clara violación de la privacidad.

La falta de transparencia y supervisión es casi tan preocupante como la propia actividad. La naturaleza centralizada del ICDC oculta de forma efectiva el tipo, alcance y profundidad de las actividades de adquisición de datos. Sin mecanismos de supervisión sólidos, existe un alto riesgo de uso indebido y extralimitaciones por parte de los organismos que componen la Comunidad de Inteligencia. Esto constituye, nuevamente, una posible violación de los derechos ciudadanos.

La adquisición incontrolada de CAI erosionará las protecciones establecidas por la Cuarta Enmienda. La investigación profunda de personas estadounidenses sin órdenes judiciales o aprobaciones legales desafía las protecciones que dicha enmienda otorga contra registros e incautaciones irrazonables. Las operaciones del ICDC sientan un precedente que permite eludir estas salvaguardas constitucionales.

Existe un alto potencial de abuso. La consolidación de datos personales en una plataforma centralizada incrementa el riesgo de accesos no autorizados y mal uso. En ausencia de estrictos controles de acceso y mecanismos de auditoría, aumenta significativamente la probabilidad de abuso de información sensible.

Equilibrio entre la Seguridad Nacional y las Protecciones Constitucionales

La justificación principal del ICDC es el fortalecimiento de la seguridad nacional mediante la mejora de las capacidades de inteligencia. Sus defensores argumentan que el acceso simplificado a la CAI permite una detección y respuesta más eficaz ante amenazas. No obstante, esto debe equilibrarse con los derechos fundamentales consagrados en la Constitución. La Cuarta Enmienda funciona como un control esencial del poder gubernamental, garantizando que los ciudadanos estén protegidos contra intromisiones injustificadas en su vida privada. El enfoque del ICDC hacia la adquisición de datos elude los procesos legales tradicionales y, por tanto, representa una amenaza significativa a dichas protecciones. Además, el potencial de desviación de misión genera inquietudes graves sobre las implicaciones a largo plazo para las libertades civiles. Sin límites claros y supervisión efectiva, el ICDC podría convertirse en una herramienta de vigilancia omnipresente, minando la confianza pública en las instituciones gubernamentales. El Panóptico habrá llegado.

Protección de la Privacidad

Si bien existen peligros, también hay medidas de control que pueden mitigar los riesgos asociados al ICDC. El establecimiento de marcos legales claros es un buen punto de partida. La legislación debe definir el alcance y las limitaciones de las actividades de recolección de datos, asegurando que se ajusten a las protecciones constitucionales y los derechos de privacidad. Se deben instaurar mecanismos de supervisión sólidos, similares a los que rigen bajo la FISA. Órganos de supervisión independientes deben estar facultados para monitorear las operaciones del ICDC, realizar auditorías y hacer cumplir el cumplimiento de los estándares legales y éticos. La transparencia debe ser la norma rectora. La comunidad de inteligencia debe estar obligada a emitir informes periódicos sobre las actividades de adquisición de datos, incluyendo los tipos de datos recopilados, los fines para los que se utilizan y las salvaguardas implementadas para proteger la privacidad. Dichos informes pueden y deben servir como base para entablar un diálogo con organizaciones de la sociedad civil, defensores de la privacidad y el público en general. La apertura en este aspecto fomentará un discurso más informado sobre el equilibrio entre seguridad nacional y los derechos de las personas y grupos afectados por la actividad OSINT.

El Consorcio de Datos de la Comunidad de Inteligencia representa un cambio significativo en la forma en la cual la comunidad de inteligencia estadounidense accede y utiliza la información comercialmente disponible. Si bien ofrece beneficios potenciales para la seguridad nacional, también conlleva riesgos sustanciales para la privacidad y los derechos constitucionales de los ciudadanos estadounidenses. Para garantizar que la búsqueda de seguridad no se realice a costa de las libertades civiles, es imperativo establecer marcos legales claros, supervisión rigurosa y prácticas transparentes que respeten los principios de una sociedad democrática.

~ C. Constantin Poindexter, MA en Inteligencia, Cert. de Posgrado en Contrainteligencia, JD, CISA/Cert. OSINT de NCISS, BFFOC del DoD/DoS

Referencias

  • Office of the Director of National Intelligence. (2025). OSINT Contract Framework. Obtenido de ODNI Document
  • The Intercept. (22 de mayo de 2025). US Plans Data Portal to Expand Warrantless Surveillance. Obtenido de The Intercept
  • Wired. (24 de mayo de 2025). Security News This Week: The US Is Building a One-Stop Shop for Buying Your Data. Obtenido de Wired
  • Brennan Center for Justice. (s.f.). The Intelligence Community’s Policy on Commercially Available Data Falls Short. Obtenido de Brennan Center
  • U.S. Senate. (2023). Privacy Act of 1974. Obtenido de Wikipedia
  • U.S. Senate. (2023). Foreign Intelligence Surveillance Act. Obtenido de Wikipedia
  • Wired. (20 de noviembre de 2023). Secretive White House Surveillance Program Gives Cops Access to Trillions of US Phone Records. Obtenido de Wired
  • AP News. (28 de septiembre de 2023). A Key US Government Surveillance Tool Should Face New Limits, a Divided Privacy Oversight Board Says. Obtenido de AP News
  • Time. (15 de marzo de 2024). Inside the White House Program to Share America’s Secrets. Obtenido de Time
  • AP News. (10 de marzo de 2024). Book Review: ‘Means of Control’ Charts the Disturbing Rise of a Secretive US Surveillance Regime. Obtenido de AP News
Share this post:

Intelligence Community Data Consortium: OSINT, Balancing National Security and Civil Liberties

OSINT, inteligencia, CNI, contrainteligencia, contraespionaje, espionaje, c. constantin poindexter

The Office of the Director of National Intelligence (ODNI) has unveiled plans for the Intelligence Community Data Consortium (ICDC), a centralized platform designed to streamline the acquisition of commercially available information (CAI) by the Intelligence Community. This initiative aims to enhance data accessibility and efficiency across the I.C. However, the ICDC has sparked a traditional FISA-like debate regarding its implications for the privacy rights of American citizens and the potential erosion of constitutional protections.

Understanding the ICDC Initiative

The ICDC represents a concerted effort by the U.S. intelligence community to modernize and centralize the procurement of CAI. According to the official solicitation documents, the ICDC is envisioned as a “marketplace to query and interact with vendor holdings,” emphasizing a “zero-copy” architectural goal where data is queried in place on vendor systems rather than being copied to government servers. This approach is intended to reduce data duplication and enhance operational efficiency. The platform is designed to operate entirely at the unclassified computing level, with all work remaining unclassified. It will offer multiple data interaction options, including indexed GUI/WUI search, API calls, bulk data access, and external web portal login options. The use of open-source code and adherence to industry standards such as OpenAPI Specifications are highlighted here in order to ensure flexibility and prevent vendor lock-in.

Potential Dangers to Innocent Americans

While the ICDC aims to improve intelligence operations, it raises several concerns regarding the privacy of innocent Americans.

The scope of data collection is problematic. Scooping up masses of information about persons absolutely free of suspicion or interest to the I.C. is the proverbial eight-hundred-pound gorilla in the room. The ICDC facilitates access to vast amounts of personal data, including location information, biometric records and online activities, without the need for traditional legal authorizations such as those provided by the FISA Court. This expansive data collection will likely encompass information about individuals not under any suspicion, a clear privacy infringement.

A lack of transparency and oversight is second only to the activity itself. The centralized nature of the ICDC effectively obscures the nature, depth and breadth of acquisition activities. Without robust oversight mechanisms, there is a risk of misuse and overreach by I.C. member agencies. Again, this is potentially an infringement on the rights of citizens.

Uncontrolled CAI acquisition will erode Fourth Amendment protections. Deep investigation of U.S. persons without warrants or court approvals challenges the protections afforded by the Fourth Amendment, a guard against unreasonable searches and seizures. The ICDC’s operations set up a precedent for circumventing these constitutional safeguards.

There is a high potential for abuse. The consolidation of personal data in a centralized platform increases the risk of unauthorized access and misuse. In the absence of stringent access controls and auditing mechanisms, there is a heightened potential for abuse of sensitive information.

Balancing National Security and Constitutional Protections

The primary justification for the ICDC is the enhancement of national security through improved intelligence capabilities. Proponents argue that streamlined access to CAI enables more effective threat detection and response. However, this must be balanced against the fundamental rights enshrined in the Constitution. The Fourth Amendment serves as a critical check on government power, ensuring that citizens are protected from unwarranted intrusions into their private lives. The ICDC’s approach to data acquisition bypasses traditional legal processes and thus poses a significant threat to these protections. Further, the potential for mission creates significant concerns about the long-term implications for civil liberties. Without clear boundaries and oversight, the ICDC could become a tool for pervasive surveillance, undermining public trust in government institutions. The Panopticon will have arrived.

Safeguarding Privacy

While perils exist, so do controls that can mitigate the risks associated with the ICDC. The establishment of clear legal frameworks is a good start. Legislation must define the scope and limitations of data collection activities, ensuring that they align with constitutional protections and privacy rights. Robust oversight mechanisms, much like FISA must be established. Independent oversight bodies must be empowered to monitor the ICDC’s operations, conduct audits, and enforce compliance with legal and ethical standards. Transparency must be the guiding rule. The intelligence community should be obligated to provide regular reports on data acquisition activities including the types of data collected, the purposes for which it is used, and the safeguards in place to protect privacy. Those reports can and should be the basis for engagement with civil society organizations, privacy advocates, and the public. Being open about this will foster a more informed discourse on the balance between national security and those individuals and groups affected by the OSINT activity.

The Intelligence Community Data Consortium represents a significant shift in how the U.S. intelligence community accesses and utilizes commercially available information. While it offers potential benefits for national security, it also poses substantial risks to the privacy and constitutional rights of American citizens. To ensure that the pursuit of security does not come at the expense of civil liberties, it is imperative to establish clear legal frameworks, robust oversight, and transparent practices that uphold the principles of a democratic society.

~ C. Constantin Poindexter, MA Intelligence, Grad. Cert. Counterintelligence, JD, CISA/NCISS OSINT cert., DoD/DoS BFFOC

References

Office of the Director of National Intelligence. (2025). OSINT Contract Framework. Retrieved from ODNI Document

The Intercept. (2025, May 22). US Plans Data Portal to Expand Warrantless Surveillance. Retrieved from The Intercept Article

Wired. (2025, May 24). Security News This Week: The US Is Building a One-Stop Shop for Buying Your Data. Retrieved from Wired Article

Brennan Center for Justice. (n.d.). The Intelligence Community’s Policy on Commercially Available Data Falls Short. Retrieved from Brennan Center Article

U.S. Senate. (2023). Privacy Act of 1974. Retrieved from Wikipedia Article

U.S. Senate. (2023). Foreign Intelligence Surveillance Act. Retrieved from Wikipedia Article

Wired. (2023, November 20). Secretive White House Surveillance Program Gives Cops Access to Trillions of US Phone Records. Retrieved from Wired Article

AP News. (2023, September 28). A Key US Government Surveillance Tool Should Face New Limits, a Divided Privacy Oversight Board Says. Retrieved from AP News Article

Time. (2024, March 15). Inside the White House Program to Share America’s Secrets. Retrieved from Time Article

AP News. (2024, March 10). Book Review: ‘Means of Control’ Charts the Disturbing Rise of a Secretive US Surveillance Regime. Retrieved from AP News Article

Share this post:

What is OSINT all about?

OSINT, IMINT, constantin poindexter, carlyle poindexter, masters in intelligence studies, counterintelligence

OSINT is as ancient as written word. I suppose that there were cuniform tablets that were exchanged between Phoenician government functionaries, both public and sensitive that adversaries coveted. The Greeks were particularly good at intelligence. There is a really good book about it written by Frank Santi Russell. It’s super interesting to see what value a first-generation democracy put on information gathering. What is without question is that OSINT is valuable. Wild Bill Donovan said, “Even a regimented press will, again and again, betray their nation’s best interests to a painstaking observer.”

Like the other INTs, there are some definitions that most practitioners have settled on to describe OSINT. Information collected from the “wherever” is generally not intelligence. It is data or simply information. Intelligence is generally an analyzed and polished product that CONTAINS information. The Department of Defense defines OSINT under ¨§931 of Title Nine, “Open-source intelligence (OSINT) is intelligence that is produced from publicly available information and is collected, exploited, and disseminated in a timely manner to an appropriate audience for the purpose of addressing a specific intelligence requirement.” (50 U.S.C.) The Hassan and Hjazi publication which offered this statutory definition verbatim HOWEVER they added what I think are some really important distinctions of what composes OSINT (“components” as Dr. Saar has highlighted.), as follows, “, . . .

*Open-source data
*Open-source information
*Open-source intelligence
*Validated open-source intelligence”

These components are important not only for context and precedence, adhering to the currently accepted intelligence cycle, etc., but also to offer a framework for practitioners of other INTs to identify where to offer input, and from whence to retrieve reliable and timely data, information and/or intelligence for their own purposes.

OSINT has progressed over time, but not in its essential nature. OSINT has essentially existed since cavemen roamed the earth. Ug of the ooga booga tribe probably eavesdropped on conversation between the huti huchi tribesemen to discover where the best mastodon hunting ground was. Obviously, this oversimplifies something that is actually quite sophisticated now, . . . or is it? We now have written word and motions images á la the ubiquitous YouTube, but is observation and pondering (analysis) of those observations really an innovation? My position is that OSINT really hasn’t changed at all. The medium for presentation (or mass dissemination) of information, the sophistication of the sensors that we use to collect information, the volume of collection and the high-speed computer-driven analysis of the information have changed, NOT OSINT.

There are clear advantages to the development and deployment of a rigorous OSINT capability. First and foremost is risk. Passive OSINT presents almost no risk at to either the discovery of the inquiry and the fallout if collection is discovered. Done properly, OSINT projects are discovered by the betrayal of a practitioner. An intelligence manager must consider the likelihood of discovery and the severity of loss due to discovery. OSINT falls low on the risk index. It’s just smart business.

Another big benefit but as the same time, a serious challenge is the volume of data or information. The benefit of volume is generally an increased reliability of product. There are plenty of disinformation operations in the world’o’sphere but in a massive pool of data an enormous effort and resources are required to drown out factual information. Also, a really big pool offers the input of a broad variety of assets or sources. The diversity REALLY helps stabilize analyst’s effort to draw reliable conclusions. The negative of course is how to warehouse and process the huge, HUGE amount of data that an OSINT mission or tasking might produce. This is and will be solved by quantum computing but the OSINT discipline also benefits from the less rigorous processing that a technical INT might require. The Norton piece spoke specifically to the “volume” conundrum along with the vetting challenge. “OSINT is challenging because of its volume and because each piece of information must be verified or “vetted,” often in unique ways.” (Norton, 2011, p. 66)

Among the list of advantages, “shareability” is also important. Not only is dissemination of OSINT product helpful and perhaps imperative among members of the Intelligence Community. It can also be superlatively supportive our allies, the countries with whom we share special liaison or allied service relationships. There is little risk to “sources and methods” with regard to OSINT. The real risk of improper or over-dissemination of OSINT is tipping our hand as to what is important to us AND prejudicing the asset or source, ie., U.S. Adversary: “You are looking at “x”? Oh! You must have some strategic or tactical interest in “x”! We’d better look into shutting off that faucet and since it’s important to YOU, then we’d better figure out a countermeasure.” Russian FIS does this, . . . regularly.

There are some other positive qualities of OSINT, i.e., gives a baseline for understanding the results of more sensitive information collected clandestinely; timeliness, as open sources are often in open competition as to who can “break the story” first; a great enhancement to cultural and ethnic understanding, etc., however the three main attributes above I think are the most valuable and relevant.

I need to give a hat-tip to a crowdsourcing article. The author has offered a neat little diagram to identify it but the author’s statement, “Crowdsourced Intelligence is arguably a separate collection discipline from HUMINT or OSINT collection.” (Stottlemyre, 2015) I feel is prescient. I’m not sure that this fits neatly within the OSINT discipline, most especially if the source is a member of an adversarial government, military or FIS. There are also a lot of wildcards in here, i.e., crowd motivation, crowd identity, or whether it’s really a “crowd” or not. This one merits a deeper look.

Waters, Nick, “Google Maps Is a Better Spy Than James Bond”, Foreign Policy, September 25th, 2018. https://foreignpolicy.com/2018/09/25/google-maps-is-a-better-spy-than-james-bond/#:~:text=In%20the%20words%20of%20William,interests%20to%20a%20painstaking%20observer.%E2%80%9D

Norton, Dr. R.A., “Guide to Open Source Intelligence: A Growing Window into the World”, Journal of Intelligence Studies”, vol. 18, no. 2, Winter/Spring 2011

Stottlemyre, Steven A., “HUMINT, OSINT, or Something New? Defining Crowdsourced Intelligence”, International Journal of Intelligence and Counterintelligence, vol. 28, iss. 3, 2015

Share this post: