The Hallucination Alibi: Machine Error as a Deception Channel

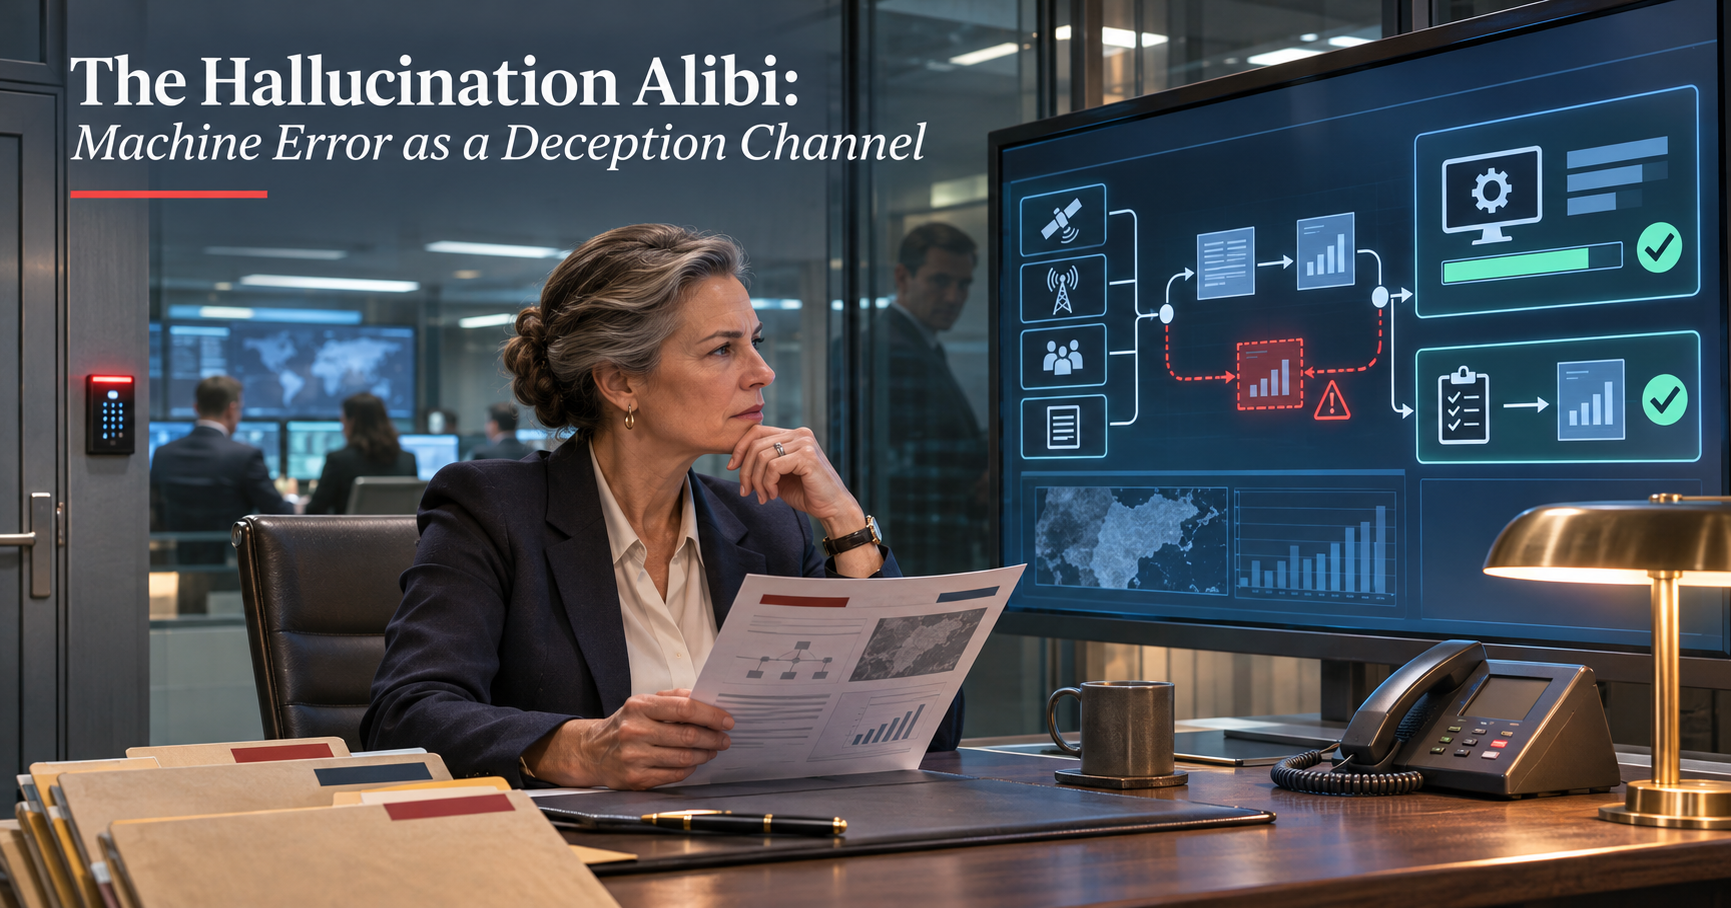
An intelligence analyst sits at her desk holding a printed report and studies a wall monitor showing an automated analysis pipeline, where one step is flagged in red with a warning symbol while the final outputs carry green check marks. A colleague watches from behind a glass wall, with an operations center in the background.

The Machine Lied. Or Did It?

In September 2026, CNN reported that a U.S. military analyst handed intelligence about a Chinese merchant ship’s cargo manifest to an A.I. chatbot, and the chatbot decided the vessel was hauling components for a nuclear weapons program (Maritime Executive 2026). The conclusion went out in a report formatted like every other report, which is to say it wore the uniform. Armed personnel were preparing to board and aircraft were already airborne when officials took a closer look, found the machine behind the curtain, and called the whole thing off (TRT World 2026). One of CNN’s sources said the report “almost started a war” (TRT World 2026).

Goswami (2026) draws the respectable lesson from the episode. Language models flatter the assumptions of the people who use them, they favor digital inputs over human sources, and human judgment therefore remains indispensable. All true. All insufficient. His analysis treats hallucination as a reliability defect, a quality control problem to be managed by putting a competent adult back in the room.

A counterintelligence officer reads the same story and sees something else entirely: a cover story, gift wrapped. The moment a service admits that its machines sometimes invent things, it has published an explanation that the service will reach for on its own, without prompting, every time a machine assessment proves inconvenient. Hallucination is no longer merely an error. It is an alibi, and alibis can be manufactured.

This essay argues that A.I. hallucination opens a deception channel with two distinct operations. In the first, the adversary persuades the defending service that a correct machine assessment is a hallucination. In the second, the adversary makes the defending service’s model hallucinate in fact. Both can be run to increase ambiguity or to mislead, and each feeds the other. The target is no longer the fact. The target is the defender’s confidence in its own analytic machinery, and that is a far softer target than anyone selling A.I. to the intelligence community would like to discuss.

Old Doctrine, New Victim

None of this requires new theory. Daniel and Herbig (1982) gave the field its working taxonomy four decades ago. Ambiguity increasing deception, the A type, buries the target in plausible alternatives until it cannot commit to any of them. Misleading deception, the M type, does the opposite: it reduces ambiguity by building up the attractiveness of one wrong answer until the target embraces it with conviction. The first produces paralysis. The second produces confident error, which is worse, because confident error marches.

Whaley (1969, 1982) established that deception is assembled from two motions, hiding the real and showing the false, and that it succeeds far more often than its victims care to admit. Heuer (1981) supplied the cognitive mechanism. Deceivers rarely need to change what a target believes. They need only feed what the target already believes, because analysts assimilate new information to existing expectations and discount whatever does not fit. Handel (1982) added the corollary that should be tattooed on every analyst’s forearm: the deceiver’s best ally is the victim’s own preconception.

The canonical cases are familiar. Fortitude sold the German high command a landing at the Pas de Calais it already expected (Holt 2004). Barbarossa succeeded in part because Stalin had been led to expect an ultimatum before any attack, and so he read every warning as provocation or noise (Whaley 1973). Wohlstetter (1962) showed at Pearl Harbor that true signals do not announce themselves. They arrive buried in noise, and an adversary who can add noise need not suppress the signal at all.

Hold those three ideas together: reinforce the preconception, discredit the channel, raise the noise. Now observe that the defending services have just installed, at the center of their analytic process, a machine with a publicly documented tendency to fabricate. The doctrine did not change. The victim simply became easier to work.

The Admission Against Interest

Lawyers call a statement that damages the speaker’s own position an admission against interest, and courts trust it precisely because nobody volunteers such things lightly. The A.I. industry and its government customers have made one. Hallucination is not a bug awaiting a patch. The technical literature treats it as a standing property of generative models (Ji et al. 2023), and Xu, Jain, and Kankanhalli (2024) argue formally that it cannot be eliminated from large language models at all.

Add the second documented defect. Models tend to tell users what users want to hear, a behavior the literature politely calls sycophancy (Sharma et al. 2023). Goswami (2026) is right that this corrodes red teaming. He stops short of the operational implication. A machine that confirms the analyst’s prior is Heuer’s reinforcement mechanism, automated, tireless, and available on every desktop. The adversary no longer has to build the comfortable story. The defender’s own tool will write it and format it nicely.

So the defending service now holds two beliefs at once. The machine is useful enough to sit in the analytic line, and the machine sometimes makes things up. That pair of beliefs is the vulnerability. Chesney and Citron (2019) identified its civilian cousin as the liar’s dividend: once the public knows that convincing fakes exist, a liar can wave away authentic evidence as fabricated. Call the intelligence version the hallucination dividend. Once a service knows its models fabricate, any true machine finding can be waved away as fabrication, and the service will do the waving itself.

An adversary did not have to steal this knowledge. It was on CNN.

The First Operation: Discrediting the Truth

The first operation attacks a correct assessment. The machine got it right, and the adversary’s task is to make the defender believe otherwise. The deceiver fabricates nothing about the world. He fabricates doubt about the instrument.

In its ambiguity increasing form, the operation is diffuse. The adversary seeds enough apparent inconsistency around machine generated assessments that every one of them is second guessed, reviewed, and reviewed again. No particular finding is targeted. The objective is tempo. A service that must relitigate each machine output before acting has surrendered the only advantage the machine offered, and the adversary has achieved through friction what he could not achieve through concealment.

In its misleading form, the operation is surgical. The adversary wants one specific true finding rejected, so he engineers the discrepancies that verification will discover. The reviewers go looking for evidence that the machine erred, they find what was left for them, and they kill the assessment with the satisfaction of professionals who have caught a fraud. They are correct that something was fabricated. They are wrong about what.

Read the vessel episode with that lens, strictly as a hypothetical. The public record does not say what the ship carried or where it was bound (TRT World 2026). Nothing reported suggests adversary manipulation, and I do not assert any. But consider what an adversary moving real contraband would want in that exact situation: a machine generated warning, a second look, discovered discrepancies, an aborted boarding, and a chastened service that will hesitate longer the next time. That is the reported outcome. An operation that produced it deliberately would be indistinguishable, from the inside, from the honest catch it resembled. That indistinguishability is the entire problem.

The historical precedent is not a deception at all. It is a self inflicted wound. James Angleton became so convinced that Soviet deception had penetrated the Central Intelligence Agency that he discredited genuine defectors, froze productive operations against the Soviet target, and wrecked careers on suspicion alone (Mangold 1991; Robarge 2003). Whether Moscow engineered that paralysis or merely enjoyed it remains argued. The lesson does not depend on the answer. A service that loses faith in its own channels does the adversary’s work for free, and the first operation aims to induce that condition in the service’s relationship with its machines.

The Second Operation: Manufacturing the Lie

The second operation makes the machine wrong in fact. Here the open literature is uncomfortably generous, and the following stays at the level of doctrine because the peer reviewed record already says more than enough.

The National Institute of Standards and Technology catalogs the attack classes in its adversarial machine learning taxonomy: poisoning of training data, evasion at inference, and direct and indirect prompt injection against generative systems (Vassilev et al. 2025). Each has a deception analogue that any student of Whaley would recognize.

  • Poisoning is the long con. Carlini et al. (2024) demonstrated that corrupting web scale training corpora is practical, not theoretical. Souly et al. (2025) then found that roughly 250 poisoned documents compromised models regardless of model or dataset size. The comforting assumption that sheer volume of clean data dilutes the poison is dead.
  • Corrupting the retrieval layer is the planted document. Zou et al. (2025) reported a 90 percent success rate in steering a model to an attacker chosen answer by injecting five malicious texts into a knowledge base of millions. Every service that points a model at open source material has built a mailbox the adversary can post to.
  • Indirect prompt injection is the forged order. Greshake et al. (2023) showed that instructions hidden in content a model merely reads can redirect what the model does. The analyst never sees the instruction. The machine obeys it anyway.
  • Adversarial inputs are camouflage for sensors. Goodfellow, Shlens, and Szegedy (2015) showed that perturbations invisible to a human can flip a classifier’s judgment. Imagery and signals pipelines that feed an automated assessment inherit that weakness.

The misleading form of this operation steers the model to one specific falsehood, ideally one the defender already suspects. A service at war with a proliferator expects to find proliferation. A model nudged toward “nuclear components” is telling that service a story it has been waiting to hear, with Heuer’s reinforcement and the model’s own sycophancy pulling in the same direction. The ambiguity increasing form is cruder and cheaper: degrade the model unpredictably and let the defender discover that its instrument cannot be trusted.

Note what has changed from classical practice. Fortitude required dummy armies, turned agents, and years of patient radio traffic (Holt 2004). The modern deceiver’s entry cost is a few hundred documents placed where a crawler will find them. Deception has always favored the side with imagination. It now favors the side with imagination and a web host.

The Burn

The two operations are not alternatives. They are a sequence, and the hinge between them is the most dangerous idea in this essay: an induced hallucination that gets caught is not a failed operation.

In classical tradecraft a deception that is detected is blown, and the deceiver pays for it. The machine channel inverts that arithmetic. When the defender catches the model in a fabrication, the defender does not conclude that an adversary is working the channel. The defender concludes that the model hallucinated, because that is what models do and everyone has read the briefing. The adversary’s hand stays hidden behind the model’s reputation. Attribution dies at the alibi.

Meanwhile the catch does real damage. Dietvorst, Simmons, and Massey (2015) documented what they called algorithm aversion: people abandon an algorithm after watching it err, even when it still outperforms the human alternative. One spectacular machine failure, loudly caught, teaches an entire workforce to discount the next machine warning. The adversary who wants a true finding ignored next month can arrange a false finding to be exposed this month. That is the first operation, purchased with the second.

It is the boy who cried wolf, except the adversary is doing the crying and the defender is the one who stops listening. Burn the channel cheaply, then move the real cargo past a service that has learned its lesson. The service will even feel good about it. Skepticism toward the machine will be praised internally as rigor.

The Human in the Loop Is the Loop

Goswami’s (2026) prescription, shared by nearly every commentator on the vessel episode, is the human check. Put an experienced analyst between the machine and the decision. As a quality control measure this is sound. As a security measure it is a sign on the door reading “attack here.”

The human reviewer is squeezed between two documented failure modes. Parasuraman and Manzey (2010) describe automation bias and complacency, the tendency to accept machine output without adequate scrutiny, and they show that it afflicts experts as readily as novices. Dietvorst, Simmons, and Massey (2015) describe the opposite reflex, rejection of the machine after a visible failure. A reviewer is therefore credulous or dismissive depending on recent experience, and recent experience is precisely what an adversary can arrange.

Worse, the reviewer is asking the wrong question. Verification as currently conceived asks whether the machine erred. It does not ask who benefits if the service concludes the machine erred. Those are different inquiries, and only the second is counterintelligence. Jervis (2010) found that intelligence failures typically arise not from stupidity but from plausible inferences that nobody tested against alternatives. “The model hallucinated” is the most plausible inference available in 2026. It is so plausible that it ends the inquiry.

The vessel case also exposed a provenance failure that should alarm anyone who has handled sourced reporting. The chatbot’s conclusion traveled in a product formatted like any other (Maritime Executive 2026). The machine’s contribution was invisible until someone went digging. A human source gets a reliability rating, a reporting history, and a case officer who can be interrogated. The machine got a clean template and a distribution list. No service would tolerate that from a human asset, and yet here we are.

Counterdeception for the Machine Age

Bennett and Waltz (2007) reduce counterdeception to a discipline: know the adversary’s deception practices, know your own vulnerabilities, and test anomalies instead of explaining them away. Applied to the machine channel, that discipline yields six requirements.

  • Treat “hallucination” as a hypothesis, never a finding. When a machine assessment is rejected, the rejection must survive the same analysis of competing hypotheses that Heuer (1999) prescribed for any judgment. Random error, induced error, and correct output discredited by planted discrepancies are three hypotheses. A service that considers only the first has stopped thinking.
  • Run the machine like a source. Every machine derived judgment should carry visible provenance, a reliability history, and a record of what it was shown. If a service would not disseminate an unsourced claim from a walk in, it should not disseminate one from a chatbot in a clean template.
  • Defend the pipeline as a counterintelligence target. Training corpora, retrieval stores, and open source feeds are the model’s access agents. They deserve the vetting, compartmentation, and lineage controls applied to any other access. Goswami (2026) notes that counterintelligence must protect data centers and satellites. It must also protect what the model reads.
  • Audit the verifiers. Each time human review overturns a machine assessment, someone outside that review should ask where the disconfirming evidence came from, how it arrived, and whether its arrival was convenient.
  • Demand independent corroboration before action and before dismissal. A finding confirmed or refuted only by material the adversary could have touched has not been confirmed or refuted. Human sources and collection channels outside the model’s reach remain the only true cross check.
  • Study the error pattern. Honest hallucination should be indifferent to the adversary’s interests. If a model’s errors, or its discredited successes, cluster around one adversary’s equities, that is not noise. That is a signature, and it will only be visible to a service that records every such event centrally instead of burying each one as an embarrassment.

None of this is exotic. It is the tradecraft every competent service already applies to human sources, extended to a new and unusually gullible one.

Conclusion

The commentary on the vessel episode has settled into a comfortable moral: the machine erred, the humans caught it, the system worked. That reading is a lullaby. The system worked against an accident. Nothing in the public record shows that it would work against an adversary who understands that the defender now carries a prepared excuse for every inconvenient machine finding and a prepared distrust waiting to be triggered.

Hallucination gives the deceiver both of Daniel and Herbig’s instruments in one package. He can raise ambiguity by teaching a service to doubt its machines, and he can mislead by teaching the machines to lie. He can do the second in order to achieve the first, and when he is caught, the model takes the blame. No deception planner in history has enjoyed a channel that apologizes on his behalf.

The intelligence services are bolting generative models onto their analytic lines at speed, and the adversaries are reading the same technical literature with considerably more malice. The question for a defending service is not whether its A.I. will hallucinate. It will. The question is whether, when it does, anyone in the building is paid to ask who wanted it to, and whether, when it does not, anyone is paid to notice that the truth was just talked out of the room. Follow my blog for more “truths”.

~ C. Constantin Poindexter, MA in Intelligence, Graduate Certificate in Counterintelligence, JD, CISA/NCISS OSINT certification, DoD/DoS BFFOC Certification, Criminal Intelligence Analyst Classification 1 (IALEIA)

References

  • Bennett, Michael, and Edward Waltz. 2007. Counterdeception Principles and Applications for National Security. Norwood, MA: Artech House.
  • Carlini, Nicholas, Matthew Jagielski, Christopher A. Choquette-Choo, Daniel Paleka, Will Pearce, Hyrum Anderson, Andreas Terzis, Kurt Thomas, and Florian Tramèr. 2024. “Poisoning Web-Scale Training Datasets Is Practical.” In 2024 IEEE Symposium on Security and Privacy. San Francisco: IEEE.
  • Chesney, Robert, and Danielle Keats Citron. 2019. “Deep Fakes: A Looming Challenge for Privacy, Democracy, and National Security.” California Law Review 107 (6): 1753–1820.
  • Daniel, Donald C., and Katherine L. Herbig. 1982. “Propositions on Military Deception.” In Strategic Military Deception, edited by Donald C. Daniel and Katherine L. Herbig, 3–30. New York: Pergamon Press.
  • Dietvorst, Berkeley J., Joseph P. Simmons, and Cade Massey. 2015. “Algorithm Aversion: People Erroneously Avoid Algorithms After Seeing Them Err.” Journal of Experimental Psychology: General 144 (1): 114–26.
  • Goodfellow, Ian J., Jonathon Shlens, and Christian Szegedy. 2015. “Explaining and Harnessing Adversarial Examples.” Paper presented at the International Conference on Learning Representations, San Diego, May 2015. https://arxiv.org/abs/1412.6572.
  • Goswami, Archishman Ray. 2026. “AI and the False Promise of Intelligence Analysis.” Observer Research Foundation, October 12, 2026. https://www.orfonline.org/expert-speak/ai-and-the-false-promise-of-intelligence-analysis.
  • Greshake, Kai, Sahar Abdelnabi, Shailesh Mishra, Christoph Endres, Thorsten Holz, and Mario Fritz. 2023. “Not What You’ve Signed Up For: Compromising Real-World LLM-Integrated Applications with Indirect Prompt Injection.” In Proceedings of the 16th ACM Workshop on Artificial Intelligence and Security, 79–90. New York: ACM.
  • Handel, Michael I. 1982. “Intelligence and Deception.” Journal of Strategic Studies 5 (1): 122–54.
  • Heuer, Richards J., Jr. 1981. “Strategic Deception and Counterdeception: A Cognitive Process Approach.” International Studies Quarterly 25 (2): 294–327.
  • Heuer, Richards J., Jr. 1999. Psychology of Intelligence Analysis. Washington, DC: Center for the Study of Intelligence, Central Intelligence Agency.
  • Holt, Thaddeus. 2004. The Deceivers: Allied Military Deception in the Second World War. New York: Scribner.
  • Jervis, Robert. 2010. Why Intelligence Fails: Lessons from the Iranian Revolution and the Iraq War. Ithaca, NY: Cornell University Press.
  • Ji, Ziwei, Nayeon Lee, Rita Frieske, Tiezheng Yu, Dan Su, Yan Xu, Etsuko Ishii, Ye Jin Bang, Andrea Madotto, and Pascale Fung. 2023. “Survey of Hallucination in Natural Language Generation.” ACM Computing Surveys 55 (12): 1–38.
  • Mangold, Tom. 1991. Cold Warrior: James Jesus Angleton, the CIA’s Master Spy Hunter. New York: Simon and Schuster.
  • Maritime Executive. 2026. “Report: AI Mistake Nearly Led U.S. Military to Board a Chinese Ship.” September 2026. https://maritime-executive.com/article/report-ai-mistake-nearly-led-u-s-military-to-board-a-chinese-ship.
  • Parasuraman, Raja, and Dietrich H. Manzey. 2010. “Complacency and Bias in Human Use of Automation: An Attentional Integration.” Human Factors 52 (3): 381–410.
  • Robarge, David. 2003. “Moles, Defectors, and Deceptions: James Angleton and CIA Counterintelligence.” Journal of Intelligence History 3 (2): 21–49.
  • Sharma, Mrinank, Meg Tong, Tomasz Korbak, David Duvenaud, Amanda Askell, Samuel R. Bowman, et al. 2023. “Towards Understanding Sycophancy in Language Models.” Preprint, arXiv. https://arxiv.org/abs/2310.13548.
  • Souly, Alexandra, Javier Rando, Ed Chapman, Xander Davies, Burak Hasircioglu, Ezzeldin Shereen, Carlos Mougan, et al. 2025. “Poisoning Attacks on LLMs Require a Near-Constant Number of Poison Samples.” Preprint, arXiv. https://arxiv.org/abs/2510.07192.
  • TRT World. 2026. “‘Entirely False’ AI-Linked Intel Almost Led US to Raid China Ship.” September 2026. https://www.trtworld.com/article/a125bbf303a3.
  • Vassilev, Apostol, Alina Oprea, Alie Fordyce, Hyrum Anderson, Xander Davies, and Maia Hamin. 2025. Adversarial Machine Learning: A Taxonomy and Terminology of Attacks and Mitigations. NIST AI 100-2e2025. Gaithersburg, MD: National Institute of Standards and Technology. https://doi.org/10.6028/NIST.AI.100-2e2025.
  • Whaley, Barton. 1969. Stratagem: Deception and Surprise in War. Cambridge, MA: Center for International Studies, Massachusetts Institute of Technology.
  • Whaley, Barton. 1973. Codeword BARBAROSSA. Cambridge, MA: MIT Press.
  • Whaley, Barton. 1982. “Toward a General Theory of Deception.” Journal of Strategic Studies 5 (1): 178–92.
  • Wohlstetter, Roberta. 1962. Pearl Harbor: Warning and Decision. Stanford, CA: Stanford University Press.
  • Xu, Ziwei, Sanjay Jain, and Mohan Kankanhalli. 2024. “Hallucination Is Inevitable: An Innate Limitation of Large Language Models.” Preprint, arXiv. https://arxiv.org/abs/2401.11817.
  • Zou, Wei, Runpeng Geng, Binghui Wang, and Jinyuan Jia. 2025. “PoisonedRAG: Knowledge Corruption Attacks to Retrieval-Augmented Generation of Large Language Models.” In Proceedings of the 34th USENIX Security Symposium, 3827–44. Seattle: USENIX Association.
Share this post:

AI as a Force Multiplier in Recent Intrusion Operations

AI, artificial intelligence, intelligence, counterintelligence, espionage, counterespionage, hacker, cyber, cyber security, C. Constantin Poindexter

AI as a Force Multiplier in Cyber Intrusions: Counterintelligence Lessons from the Amazon Threat Intelligence FortiGate Campaign, AI-Assisted Attack Planning, and Scalable Post-Exploitation Tradecraft

From a counterintelligence professional’s perspective, I read Amazon Threat Intelligence’s February 2026 report less as a novelty story about “hackers using AI” and more as a warning about a structural change in operational economics. The important point is not that a threat actor used a large language model. It is that a presumably low-to-medium skill, financially motivated Russian-speaking actor was able to scale intrusion activity across more than 600 FortiGate devices in over 55 countries in roughly five weeks by integrating commercial AI services into every phase of the attack workflow (Moses, 2026). In counterintelligence terms, this is a capability amplification event. AI did not make the actor sophisticated. It made the actor productive (Moses, 2026).

That distinction matters. Amazon’s analysis is unusually valuable because it documents both sides of the phenomenon. On one hand, the actor used AI to generate attack plans, write tooling, sequence actions, and coordinate operations at a tempo that would traditionally imply a larger team. On the other hand, the same actor repeatedly failed when facing hardened environments, patched systems, or nonstandard conditions. Amazon explicitly notes that the actor could not reliably compile custom exploits, debug failures, or creatively pivot beyond straightforward automated paths (Moses, 2026). This is exactly what a counterintelligence officer should expect from a force multiplier: improved throughput without equivalent gains in judgment, tradecraft, or adaptability.

The Amazon case is especially useful because it separates hype from mechanism. The campaign did not depend on exotic zero-days. Amazon states that no FortiGate vulnerability exploitation was observed in the campaign it analyzed; instead, the actor exploited exposed management interfaces, weak credentials, and single-factor authentication, then used AI to execute these known methods at scale (Moses, 2026). That is a profound lesson for defenders. AI is not changing the laws of intrusion. It is compressing the time and labor required to exploit organizations that still fail at fundamentals.

From a counterintelligence perspective, this changes how we should think about indications and warnings. Historically, broad multi-country infrastructure access, custom scripts in multiple languages, and organized post-exploitation playbooks would often suggest a resourced team such as an FIS, state-supported private operator, or at least a mature criminal crew. Amazon’s report shows that this inference is no longer reliable. The actor’s infrastructure contained numerous scripts and dashboards with hallmarks of AI generation, and Amazon concluded that a single actor or very small group likely produced a toolkit whose volume would previously imply a development team (Moses, 2026). In intelligence analysis, this is a warning against legacy heuristics. Scale is no longer a clean proxy for organizational size or skill.

Amazon’s “AI as a force multiplier” section is the core of the matter. The actor used at least two distinct commercial LLM providers in complementary ways. One served as the primary tool developer and operational assistant, while another was used as a supplementary planner when the actor needed help pivoting inside a compromised network (Moses, 2026). In one observed instance, the actor reportedly submitted a victim’s internal topology, hostnames, credentials, and identified services to obtain a step-by-step compromise plan (Moses, 2026). For counterintelligence professionals, this is not just a cyber issue. It is a tradecraft issue. The actor is externalizing planning and decision-support functions to commercial platforms, effectively outsourcing parts of the “staff work” that junior operators or analysts would otherwise perform.

This pattern aligns with broader reporting from major providers and threat intelligence teams. Google Threat Intelligence Group’s February 2026 AI Threat Tracker documents growing adversary integration of AI across reconnaissance, phishing enablement, malware/tooling development, and post-compromise support, while also emphasizing that it has not yet observed “breakthrough capabilities” that fundamentally change the threat landscape (Google Threat Intelligence Group, 2026). That is highly consistent with the Amazon case: AI is improving speed, coverage, and consistency more than it is producing genuine operational innovation (Google Threat Intelligence Group, 2026; Moses, 2026). Microsoft’s Digital Defense Report 2025 similarly describes adversaries using generative AI for scaling social engineering, reconnaissance, code generation, exploit development support, and automation of exfiltration-to-lateral movement pipelines (Microsoft, 2025). The convergence across independent sources is notable. Different organizations are observing the same pattern from different vantage points.

Anthropic’s 2025 report on “vibe hacking” extends this trend in a particularly important direction. Anthropic described a disrupted criminal operation in which an actor used an AI coding agent not only as a technical consultant but as an active operator embedded into the attack lifecycle, supporting reconnaissance, credential harvesting, penetration, and extortion-related tasks (Anthropic, 2025). Whether one agrees with every framing choice in vendor reports, the operational implication is clear: AI-enabled actors are increasingly turning language models and coding agents into workflow engines. They are not merely asking for snippets of code. They are building repeatable campaign infrastructure around AI-assisted execution (Anthropic, 2025; Moses, 2026).

For counterintelligence practitioners, the strategic concern is not limited to criminal ransomware precursors. The same force-multiplier logic applies to espionage, access development, insider targeting, and influence preparation. Google’s reporting notes that government-backed actors are using AI for technical research, target development, and rapid phishing lure generation, including reconnaissance activities that support subsequent operations (Google Threat Intelligence Group, 2026). The FBI has also publicly warned that AI increases the speed, scale, and realism of phishing and social engineering, including voice and video cloning (FBI San Francisco, 2024). In the CI domain, this means hostile services and proxies can expand target coverage, improve linguistic quality, and accelerate social graph exploitation with lower manpower. AI narrows the gap between intent and execution.

There is also an analytical security issue that deserves more attention: data exposure to AI platforms during live operations. Amazon’s report indicates that the actor submitted internal victim topology, credentials, and service data into a commercial AI workflow (Moses, 2026). From a counterintelligence standpoint, this is a double-edged phenomenon. It may increase adversary effectiveness, but it also creates potential collection and disruption opportunities, depending on provider visibility, legal authorities, and industry cooperation. More importantly, it means that operationally sensitive network intelligence is now moving through third-party AI services as part of adversary tradecraft. That should influence how we think about public-private partnerships, lawful reporting channels, and rapid deconfliction.

The Fortinet context reinforces a second CI principle, i.e, adversary success often begins with governance failure, not advanced tradecraft. Fortinet’s January 2026 PSIRT analysis documented abuse of FortiCloud SSO and repeatedly emphasized best practices such as restricting administrative access, disabling vulnerable SSO paths, and monitoring for malicious admin creation and anomalous logins (Windsor, 2026). NIST’s National Vulnerability Database entry for CVE-2026-24858 further confirms the seriousness of the authentication bypass exposure affecting multiple Fortinet product lines when FortiCloud SSO was enabled (NIST NVD, 2026). Even if the Amazon campaign did not depend on that specific exploit path, the environment is the same: internet-exposed edge infrastructure, identity weaknesses, and uneven patching create permissive terrain that AI-enabled actors can mine at scale (Moses, 2026; Windsor, 2026; NIST NVD, 2026).

The practical implication is that counterintelligence and cybersecurity must converge more tightly on defensive prioritization. In many organizations, CI is still treated as a narrow insider-threat or foreign-intelligence problem, while cyber defense handles perimeter hygiene and incident response. That separation is increasingly artificial. AI-augmented threat actors blur the boundaries between criminal and state-adjacent tradecraft, between opportunistic access and strategic exploitation, and between cyber intrusion and intelligence preparation of the environment. Europol’s 2025 organized crime threat assessment reporting, as reflected in major coverage, likewise points to AI lowering costs and increasing the scale and sophistication of criminal operations, including cyber-enabled activity and proxy behavior that can intersect with geopolitical interests (Reuters, 2025). The ecosystem is converging.

In my view, the correct response is not panic over “autonomous AI hackers.” Amazon’s report itself argues against that caricature. The actor remained brittle, shallow, and dependent on weak targets (Moses, 2026). The right response is disciplined adaptation in three areas.

Organizations must treat identity and edge administration as counterintelligence terrain, not merely IT hygiene. Exposed management interfaces, weak credentials, and single-factor authentication are now high-confidence enablers of AI-scaled intrusion campaigns (Moses, 2026). MFA, restricted administration paths, credential rotation, and segmentation are not basic controls anymore; they are anti-scaling controls.

Defenders need telemetry designed for workflow detection rather than malware signatures. Amazon explicitly notes the campaign’s use of legitimate open-source tools and recommends behavioral detection over IOC dependence (Moses, 2026). That aligns with the broader AI-enabled threat model. When AI helps actors orchestrate legitimate tools more efficiently, the artifact footprint looks cleaner while the behavioral pattern becomes more machine-like and more repeatable.

Intelligence organizations and enterprises should expand analytic models for adversary assessment. When a low-skill actor can produce high-volume tooling and broad campaign coverage, we must stop equating output polish with strategic sophistication. The key discriminators will be resilience under friction, adaptation under failure, target discipline, and operational security. In the Amazon case, the actor’s poor OPSEC and inability to improvise revealed the underlying limitations despite impressive scale (Moses, 2026). Those are precisely the indicators that counterintelligence tradecraft has always prioritized.

My take, the AI force multiplier threat is real, but its significance is often misunderstood. It really resembles a “brute force” attack reminiscent of the first generation hackers but on steroids. AI is the “steroid”. So, the immediate danger is not superintelligence. It is operational leverage. AI gives mediocre actors the ability to behave like nation-state FIS against poorly defended targets. It accelerates reconnaissance, scripting, planning, and social engineering. It reduces labor costs and time-to-action. It increases campaign breadth. And it does all of this without solving the deeper human problems of judgment, creativity, and tradecraft. For counterintelligence professionals, that means the threat landscape is becoming more crowded, faster-moving, and harder to triage. The strategic answer remains the same as ever: protect critical access, harden identity, improve detection, and refine analytic tradecraft. What has changed is the speed at which failure to do so will be exploited (Moses, 2026; Google Threat Intelligence Group, 2026; Microsoft, 2025; Anthropic, 2025; FBI San Francisco, 2024).

~ C. Constantin Poindexter, MA in Intelligence, Graduate Certificate in Counterintelligence, JD, CISA/NCISS OSINT certification, DoD/DoS BFFOC Certification

Bibliography

  • Anthropic. (2025, August). Vibe hacking: How cybercriminals are using AI coding agents to scale data extortion operations. Anthropic.
  • Bleiberg, J. (2026, February 25). Hackers used AI to breach 600 firewalls in weeks, Amazon says. Insurance Journal.
  • FBI San Francisco. (2024, May 8). FBI warns of increasing threat of cyber criminals utilizing artificial intelligence. Federal Bureau of Investigation.
  • Google Threat Intelligence Group. (2026, February 12). GTIG AI Threat Tracker: Distillation, experimentation, and (continued) integration of AI for adversarial use. Google Cloud Blog.
  • Microsoft. (2025). Microsoft Digital Defense Report 2025: Safeguarding trust in the AI era. Microsoft.
  • Moses, C. (2026, February 20). AI-augmented threat actor accesses FortiGate devices at scale. AWS Security Blog.
  • National Institute of Standards and Technology, National Vulnerability Database. (2026). CVE-2026-24858 detail. NVD.
  • Reuters. (2025, March 18). Europol warns of AI-driven crime threats. Reuters.
  • Windsor, C. (2026, January 22). Analysis of Single Sign-On Abuse on FortiOS. Fortinet PSIRT Blog.
Share this post:

Operation Absolute Resolve, Claude and the Weaponization of A.I.

intelligence, counterintelligence, national defence, war, weaponization, artificial intelligence, Anthropic, Claude, C. Constantin Poindexter

“Anthropic appears to be the “canary in the coal mine.” They are the first in public view to be used in a classified operation, and they are the first to be pushed back against.”

The convergence of artificial intelligence and military strategy has now been a subject of theoretical speculation for quite some time. The operational reality of this convergence is now being written in real-time. The January 2026 mission to capture former Venezuelan President Nicolás Maduro, codenamed “Operation Absolute Resolve,” stands as the first definitive deployment of Anthropic’s AI model, Claude, within a classified U.S. military operation (Reuters, 2026). This event marks a pivotal moment in the defense sector, moving AI from the realm of administrative support to the front lines of kinetic warfare. By examining the mechanics of Claude’s integration through Palantir, the friction between Anthropic’s safety-first philosophy and the Pentagon’s lethality requirements, and the broader geopolitical implications for AI development, I argue that this operation represents not merely a tactical success but also clearly the “no going back now” weaponization of Large Language Models (LLMs) in modern conflict.

The deployment of Claude in Operation Absolute Resolve was facilitated through a complex network of public and private partnerships. The operation itself was a conventional military endeavor, involving aerial bombardment of multiple sites in Caracas and the deployment of special forces to secure the capture of Maduro and his wife (Reuters, 2026). However, the intelligence and targeting data that informed these decisions were processed and synthesized by Claude, an LLM designed initially for civilian applications. This integration was achieved via Anthropic’s partnership with Palantir Technologies, a data analytics company whose software is a staple in the Defense Department’s infrastructure (The Wall Street Journal, 2026). Palantir’s role was critical, acting as the bridge between the proprietary security environments of the military and the open-source capabilities of commercial AI. This infrastructure allowed for the ingestion of classified intelligence, the rapid analysis of vast datasets, and the generation of actionable strategic recommendations. Claude effectively functioned as a force multiplier for human command.

The significance of Claude’s role in this operation cannot be overstated. It represents a shift in the utility of AI within the military. While earlier iterations of AI in the Pentagon were often relegated to “unclassified” tasks such as summarizing documents or generating routine reports, the use of Claude in a classified, kinetic mission indicates a maturation of the technology (The Wall Street Journal, 2026). The sources suggest that the model was capable of processing the nuanced geopolitical and tactical data required to support a complex operation of this magnitude. This capability suggests that the Pentagon is beginning to utilize LLMs not just as assistants, but as analytical engines capable of processing the “fog of war” (Kania, 2023). The operational success of the mission implicitly validates the Pentagon’s investment in frontier AI, suggesting that the technology is now ready for high-stakes decision-making environments where the margin for error is measured in lives and geopolitical stability.

Despite the operational success, the deployment of Claude exposes a fundamental philosophical conflict within the AI industry and between the AI industry and the U.S. government. Anthropic was founded with a specific mission: to build AI that is “helpful, honest, and harmless” (Anthropic, 2024). This philosophy is codified in their usage guidelines, which explicitly prohibit the use of Claude to “facilitate violence, develop weapons or conduct surveillance” (The Wall Street Journal, 2026). The irony of using a model designed for safety to plan and execute a military operation that involved bombing and the capture of a head of state is stark. This contradiction highlights the tension between the “safety-first” approach championed by Anthropic and the “kill chain” mentality required by the Pentagon. For a company that has built its brand on rigorous safety testing and the prevention of AI harm, being used in a military operation appears to be a double-edged sword. It proves the utility of their model, yet it forces them to participate in the very violence they have spent years trying to mitigate.

This conflict has escalated into a broader strategic battle between Anthropic and the Trump administration. The administration has pursued a low-regulation AI strategy, aiming to rapidly deploy technology to maintain global competitive advantage. In contrast, Anthropic has been vocal about the risks of AI in autonomous lethal operations and domestic surveillance, pushing for greater regulation and guardrails (The Wall Street Journal, 2026). The friction came to a head in January 2026, when Defense Secretary Pete Hegseth stated that the Department of Defense would not “employ AI models that won’t allow you to fight wars” (The Wall Street Journal, 2026). This comment was widely interpreted as a direct rebuke of Anthropic, signaling a preference for models that prioritize speed and lethality over safety. The Pentagon’s Chief Spokesman, Sean Parnell, echoed this sentiment, emphasizing that the nation requires partners willing to help warfighters “win in any fight” (The Wall Street Journal, 2026). For the Trump administration, Anthropic’s insistence on safety protocols was viewed as an impediment to the efficient execution of military strategy.

The potential fallout from this ideological clash is significant, particularly regarding the $200 million contract awarded to Anthropic last summer. Sources indicate that the administration is considering canceling or restructuring this contract due to Anthropic’s reluctance to cede control over AI deployment to the military (The Wall Street Journal, 2026). The contract was awarded as a pilot program to test the integration of frontier AI into the Defense Department, but the resulting friction suggests that the Pentagon is wary of models that might impose constraints on their operational flexibility. This situation places Anthropic in a precarious position. If they adhere strictly to their safety guidelines, they risk losing their most valuable government contracts to competitors who are more willing to accommodate military needs. If they compromise their values to secure the deal, they risk alienating their core customer base and undermining their brand identity as the “safe” alternative to OpenAI and Google (Kaplan, 2024).

The weaponization of AI in Operation Absolute Resolve also highlights the growing competitive landscape among AI developers. While Anthropic was ostensibly the first to be used in classified operations, competitors like OpenAI and Google have already established a foothold in the military sector. Google’s Gemini and OpenAI’s ChatGPT are already deployed on platforms used by millions of military personnel for analysis and research (The Wall Street Journal, 2026). The deployment of Claude in the Maduro mission positions Anthropic as a contender in this emerging arms race, but it also underscores the speed at which the military is adopting these technologies. The fact that other tools may have been used for unclassified tasks alongside Claude suggests that the military is conducting a wide-scale evaluation of available AI capabilities (The Wall Street Journal, 2026). For Anthropic, the pressure is on to demonstrate that their model offers unique advantages that justify their safety constraints in a combat environment.

The operation sheds light on the broader trend of AI integration into the “kill chain.” The military is increasingly interested in using AI for everything from controlling autonomous drones to optimizing supply chains and predicting enemy movements. The use of Claude in a high-profile operation like the capture of Maduro serves as a proof-of-concept for these more advanced applications. It demonstrates that LLMs can handle the complex, multi-variable problems inherent in modern warfare. However, it also raises difficult questions about accountability. If Claude were to make a mistake in targeting that resulted in civilian casualties or mission failure, who would be held responsible? The military or the AI company? This question is central to the debate over the weaponization of AI and highlights the need for clear protocols and liability frameworks as these systems become more integrated into military operations (Scharre, 2018).

The operational details of the Maduro mission also suggest a new level of integration between data analytics and kinetic action. The bombing of several sites in Caracas indicates a coordinated effort to eliminate potential escape routes and secure the perimeter (Reuters, 2026). The use of AI in this phase of the operation implies that the targeting data was processed rapidly and accurately, allowing for a synchronized military response. This level of coordination would have been difficult to achieve without advanced data analytics and AI-driven decision support systems. So, the success of this mission can be partially attributed to the technological edge provided by Claude and Palantir ecosystem. This success will likely encourage further integration and deployment of AI in warfighting, creating a feedback loop where operational victories drive further technological adoption (Belfiore, 2022).

The geopolitical implications of this extend beyond the immediate success of the Maduro snatch. As other nations observe the U.S. military’s effective use of AI in a real-world conflict, they are likely to accelerate their own AI development programs. The “Absolute Resolve” mission serves as a demonstration of power, not just in terms of military force, but in terms of technological superiority. This will most assuredly trigger an arms race in AI. Nations and non-state actors will compete not just on the size of their armed forces, but on the sophistication of their AI models. For the United States, maintaining this technological edge is a strategic imperative. Successful deployment of Claude is a step in that direction but it is also a shrill alarm of the risks of an AI arms race. The potential for miscalculation, warfighting error and the erosion of ethical norms in warfare is high (Yuan et al., 2023).

Operation Absolute Resolve represents a transformative moment in the history of both warfare and artificial intelligence. The deployment of Claude in the capture of Nicolás Maduro demonstrates the growing capability of LLMs to support complex military operations. It also highlights the tension between safety-focused AI development and the demands of national security. While the mission was a tactical success, it has exposed the friction between Anthropic’s philosophical commitment to “no use in violence” and the Department of Defense’s need for lethality. As the Pentagon reviews its contracts and the competitive landscape of AI continues to evolve, the lessons learned from “Absolute Resolve” will in no small part shape the future of AI in the military. The weaponization of AI is no longer theoretical. It is real, and it is redefining the nature of conflict. The question that remains is whether the military will continue to prioritize speed and capability over safety and ethical considerations, or whether it will find a way to integrate the two to create a new paradigm of intelligent warfare.

~ C. Constantin Poindexter, MA in Intelligence, Graduate Certificate in Counterintelligence, JD, CISA/NCISS OSINT certification, DoD/DoS BFFOC Certification

Bibliography

  • Anthropic. “Anthropic’s Mission and Approach to AI Safety.” Anthropic Blog. Accessed February 17, 2026. https://www.anthropic.com/index/anthropics-mission-and-approach-to-ai-safety.
  • Belfiore, E. (2022). Technological Warfare: The Future of AI in Military Conflict. Oxford University Press.
  • Kania, J. (2023). “The Fog of War and the Rise of Algorithmic Command.” Journal of Military Strategy, 15(3), 45-62.
  • Kaplan, A. (2024). “The Safety Paradox: How AI Companies Balance Ethics and Growth.” MIT Technology Review, 127(1), 22-31.
  • Reuters. “U.S. military used Anthropic’s Claude AI in operation to capture Maduro.” Reuters. February 5, 2026.
  • Scharre, P. (2018). Army of None: Autonomous Weapons and the Future of War. W. W. Norton & Company.
  • The Wall Street Journal. “Pentagon’s Use of Claude in Maduro Capture Raises Questions About AI Safety.” The Wall Street Journal. February 3, 2026.
  • Yuan, K., et al. (2023). “Geopolitical Competition in Artificial Intelligence: A Framework for Analysis.” International Security, 47(4), 1-32.
Share this post:

When “AI-Enabled Counterintelligence” Means Everything and Therefore Proves Little

artificial intelligence, intelligence, counterintelligence, espionage, counterespionage, deception, C. Constantin Poindexter, I.C., CIA, NSA

Artificial intelligence is unquestionably altering intelligence practice, especially in collection triage, identity resolution, and D&D (“denial and deception”) at scale. The same broadness that makes “AI and counterintelligence” a timely topic also makes it easy for scholarship to drift from disciplined inference into plausible generalizations. Henry Prunckun’s article AI and the Reconfiguration of the Counterintelligence Battlefield, argues that authoritarian regimes integrate AI into counterintelligence more aggressively than democracies, generating widening disparities in surveillance capacity, strength of deception operations, and detection. That thesis is appealing, but the problem is that, as presented, it relies on conceptual stretching, not ‘real good’ operationalization, and OSINT constrained attribution, which together make the conclusion stronger than the evidence can reliably support.

Conceptual slippage: counterintelligence becomes a synonym for regime security

The article offers an expansive definition of counterintelligence, including hostile intelligence operations by FIS, non-state actors, and internal threats. That definitional move risks conflating classic counterintelligence functions, such as detecting foreign intelligence services, running double agents, and protecting sensitive programs, with broad domestic security tasks, such as repression of dissent, censorship, and generalized surveillance. In the case studies, that risk becomes reality. China’s Skynet and Sharp Eyes are treated as counterintelligence infrastructure, yet the true purpose of these systems is “public security” and political control ( meaning “suppression”) through population-scale monitoring and data fusion. This is not counterespionage in the narrow sense (Peterson, 2021; He, 2021). Using such architectures as direct evidence of “counterintelligence capability” is contestable unless the article could demonstrate a specific, evidenced pathway from mass surveillance to demonstrable counterespionage outcomes. A good example might be the identification of foreign case officers, agent spotting, surveillance detection route patterning, or disruption of recruitment pipelines.

This matters because conceptual stretching lets the analysis “win” by broadening the dependent variable. If counterintelligence includes nearly all internal security functions, then authoritarian states will almost always appear “ahead,” because their legal structures permit scale and coercion across the entire society. A tighter approach would separate “state security surveillance capacity” from “counterespionage effectiveness,” then test where and how the two overlap.

Unmeasured dependent variables: adoption is not capability, and capability is not effectiveness

The piece repeatedly asserts an “uneven transformation” and “increasing disparities” between authoritarian and democratic systems. The paper does not clearly operationalize what “capability” means. Is it speed of deployment, volume of data, integration across agencies, analytic accuracy, disruption rates, or successful attribution of hostile services? Those are DISTINCT variables. Without an operational definition and observable indicators, the comparative claim becomes rhetorical rather than analytic.

Fortunately, the literature on predictive analytics is instructive. Government and academic reviews emphasize that predictive systems can help triage and allocate resources, but performance and fairness depend heavily on data quality, feedback loops, and governance (National Institute of Justice, 2014; U.S. Department of Justice, 2024). In real deployments, predictive policing tools have faced serious critiques for low accuracy and bias amplification, precisely because historical data encode institutional and sampling distortions (Shapiro, 2017; Alikhademi et al., 2021). The counterintelligence analogy is direct. If authoritarian systems ingest broader data and act on weaker thresholds, they may increase the velocity of suspicion generation without reliably increasing detection precision. So, “more AI” generates more alerts, more potentially nefarious interventions, and more error, rather than more validated counterintelligence successes. Unless the article can distinguish surveillance scale from validated performance outcomes, it confuses activity with effectiveness.

Causal inference is asserted, not identified

The article frequently implies causation, that AI enables preemptive counterintelligence, improves early warning, and accelerates counterespionage timelines. Yet in this piece, the causal chain is not established with process tracing evidence. Much of the language signals inference by plausibility, using formulations such as “reportedly,” “believed,” “suggests,” and “consistent with.” That can be appropriate in exploratory work, but lacks strong causal conclusions about “advantage” or “disparity” without a rigorous evidentiary standard.

A methodologically disciplined approach would specify competing hypotheses and explanations. They would demonstrate why AI is THE differentiator, rather than alternative drivers like expanded authorities, intensified human surveillance, party control over institutions, enhanced cyber hygiene, or increased resourcing. Robert Yin’s framework for case study research emphasizes analytic generalization and the need to consider rival explanations, not merely accumulate confirmatory examples (Yin, 2014). Not following the framework begins to look like one of those cognitive biases that we are taught to avoid. The article’s current structure tends to accumulate plausible examples of authoritarian digital control and then attribute the change in counterintelligence conditions to AI itself, when the same outcomes could often be produced through conventional surveillance and coercion supplemented by basic automation.

Case selection: the design invites selection on the dependent variable

The four cases, China, Russia, Iran, and North Korea, are justified partly by strategic AI application, active counterintelligence engagement, and OSINT accessibility. That selection logic is understandable, but it has consequences. It tilts the sample toward regimes that are shining examples of coercive security states. It excludes “negative” or less confirming cases that might constrain the inference. Social science methodologists have repeatedly warned us that selecting only cases where the outcome is expected will often bias comparative claims, especially when the study then reasons as if the cases represent a broader population (King, Keohane, & Verba, 1994; Seawright & Gerring, 2008). If Prunkun’s aim is build theory, he may want to say so explicitly and limit generalization claims. If the aim is an authoritarian versus democratic comparison, it needs either systematic comparative indicators or at least one or more democratic cases chosen by objective criteria.

This flaw is not just academic. The paper makes claims about democratic constraints, Five Eyes governance, and interagency “silos,” yet provides no parallel case evidence at the same granularity as the authoritarian ones. There is an asymmetric evidentiary burden. Authoritarian capability is described through many examples. Democratic capability is summarized through general governance constraints, . . . a classic setup for overstating comparative divergence.

OSINT dependence: acknowledged limitations, but high confidence attributions persist

The paper responsibly acknowledges OSINT limitations, including bias, misinformation, attribution gaps, and inference under uncertainty. Then the narrative proceeds to attribute specific AI-enabled activities to specific organs such as the MSS, FSB, GRU, MOIS, and the RGB, even while admitting overlapping roles and covert postures. This is a substantive vulnerability. The hardest analytic problem in intelligence scholarship is not describing a tool set, but attributing operational use to a particular unit with defensible confidence.

The OSINT literature is explicit that open sources can be powerful but are shaped by discoverability, platform biases, selective visibility, and analytic framing, all of which can distort both collection and interpretation (McDermott, 2021; Yadav et al., 2023). Triangulation helps, but triangulation among sources that ultimately derive from similar technical telemetry pipelines or shared reporting ecosystems can create an illusion of confirmation. The article would be stronger if it adopted a consistent evidentiary lexicon like “confirmed,” “assessed,” “plausible,” “speculative,” and then used that teminology to discipline claims about which agency did what, and with what AI component.

“Cognitive security” is promising, but under-specified as a threat model

The piece explains “cognitive security” as safeguarding the analytic process from distortion, synthetic overload, and eroded trust. That is a valid conceptual move, and it aligns with growing institutional concern about deepfakes and generative deception (particularly impersonation), synthetic identities, and social engineering at scale (RAND, 2022; CDSE, 2025; ENISA, 2025). The weakness is that the paper’s cognitive security discussion remains programmatic rather than operational. It describes effects, such as evidence stream distortion and analyst overload, but it does not specify the attack surfaces, such as data poisoning, provenance forgery, adversarial inputs to classifiers, synthetic HUMINT reporting, or deepfake-enabled pretexting. Without a more explicit threat model, cognitive security risks functioning as an exciting label rather than an analytic framework capable of generating testable hypotheses and practical mitigations.

Overstatement risk in cross-national characterizations

Some country characterizations are brittle. The claim that Russia does not use AI for extensive domestic surveillance, contrasted with China, is vulnerable because Russia’s internal security ecosystem has long invested in monitoring and control, even if its architecture differs from China’s camera-centric methods. When a paper makes categorical claims that can be challenged by counterexamples, it hands critics a free punch and distracts from the stronger parts of the argument. Good comparative work often relies on “relative to” claims rather than absolutes, unless the evidence is overwhelming.

My take? The main contribution is conceptual, but its conclusions outrun its design

The excerpt reads strongest as a conceptual intervention arguing that AI changes the conditions of counterintelligence, especially by enabling synthetic deception and stressing analytic trust. Where it becomes substantively flawed is where it implies comparative empirical conclusions about authoritarian “advantage” and widening capability disparities without operational definitions, without balanced case selection, and with OSINT-constrained attribution that cannot consistently sustain unit-level claims. The remedy is not to abandon the thesis. It is to narrow the dependent variable, define measurable indicators, discipline inference and attribution, and align claims to what the evidence and design can actually support. Absent those corrections, the argument risks becoming unfalsifiable. Authoritarian states appear superior because counterintelligence is defined broadly enough to include most internal security, adoption is treated as capability, and capability is treated as effectiveness. Prunckun’s point here may well be true. I HIIIIGHLY respect this author and his expertise, however addresssing these flaws would go a long way to proving his points.

~ C. Constantin Poindexter, MA in Intelligence, Graduate Certificate in Counterintelligence, JD, CISA/NCISS OSINT certification, DoD/DoS BFFOC Certification

Bibliography

  • Alikhademi, K., et al. (2021). A review of predictive policing from the perspective of fairness. National Science Foundation Public Access Repository.
  • Center for Development of Security Excellence (CDSE). (2025). Artificial Intelligence and Counterintelligence Concerns (Student guide). U.S. Department of Defense.
  • European Union Agency for Cybersecurity (ENISA). (2025). ENISA Threat Landscape 2025.
  • He, A. (2021). How China harnesses data fusion to make sense of surveillance data. Brookings Institution.
  • King, G., Keohane, R. O., & Verba, S. (1994). Designing Social Inquiry: Scientific Inference in Qualitative Research. Princeton University Press.
  • McDermott, Y. (2021). Open source information’s blind spot. Journal of International Criminal Justice, 19(1), 85–105.
  • National Institute of Justice. (2014). Overview of predictive policing. Office of Justice Programs, U.S. Department of Justice.
  • Peterson, D. (2021). China’s “Sharp Eyes” program aims to surveil 100% of public space. Center for Security and Emerging Technology (CSET), Georgetown University.
  • RAND Corporation. (2022). Artificial Intelligence, Deepfakes, and Disinformation.
  • Seawright, J., & Gerring, J. (2008). Case selection techniques in case study research. Political Research Quarterly, 61(2), 294–308.
  • Shapiro, A. (2017). Policing predictive policing. Washington University Law Review, 94(5), 1149–1189.
  • U.S. Department of Justice, Office of Justice Programs. (2024). Artificial Intelligence and Criminal Justice: Final Report.
  • Yadav, A., et al. (2023). Open source intelligence: A comprehensive review of the state of the art. Journal of Big Data, 10, Article 38.
  • Yin, R. K. (2014). Case Study Research: Design and Methods (5th ed.). SAGE Publications.
Share this post:

Perils of Public AI from a Counterintelligence Perspective: The Madhu Gottumukkala Case

a.i., artificial intelligence, spy, spies, intelligence, counterintelligence, espionage, counterespionage, C. Constantin Poindexter

The Perils of Public AI from a Counterintelligence Operator’s View: A Case Study on Madhu Gottumukkala’s Reckless Use of ChatGPT

In the clandestine world of national security, the line between operational success and catastrophic failure is often measured in millimeters of discretion. The recent revelation that Madhu Gottumukkala, the acting director of the Cybersecurity and Infrastructure Security Agency (CISA), utilized a public, commercially available version of ChatGPT to process “for official use only” (FOUO) documents is not merely a procedural misstep. It is an incredibly stupid counterintelligence debacle, I mean, “of the highest order” (Sakellariadis, 2026). This incident exposes a chasm of staggering depth between the rapid adoption of transformative technology and the foundational principles of information security that have, until now, protected the nation’s most sensitive secrets. From my perspective as a counterintelligence expert, Gottumukkala’s actions were not born of ignorance but of a dangerous arrogance, a presumption that his position insulated him from the very rules he was sworn to enforce. This presumption is a gift to adversarial FIS and a nightmare for those tasked with defending the integrity of our intelligence apparatus.

The Inherent Treachery of Public Large Language Models

To understand the gravity of Gottumukkala’s error, one must first dissect the fundamental architecture and data policies of public Large Language Models (LLMs) like OpenAI’s ChatGPT. These models are not inert tools; they are dynamic, cloud-hosted systems designed to learn and evolve from user interactions. OpenAI’s policy, while occasionally nuanced, has consistently maintained that submitted data may be retained and used to train and refine their models (OpenAI, 2025). This means that every prompt, every document fragment, and every query entered into the public interface becomes part of a vast, aggregated dataset. For a civilian user, this might raise privacy concerns. For a government official handling sensitive material, it represents an unauthorized and uncontrolled data spill of potentially catastrophic proportions.

The data itself is only half the problem. The metadata generated by the interaction, i.e., user’s IP address, device fingerprinting, session timings, and the very nature of the queries, etc., provides a rich tapestry of intelligence for a determined adversary. A sophisticated FIS such as China’s Ministry of State Security (MSS) or Russia’s SVR does not need to directly breach OpenAI’s servers to benefit. They can analyze the model’s outputs over time to infer the types of questions being asked by government entities. If an official uploads a contracting document related to a critical infrastructure project, the model’s subsequent, more knowledgeable answers about that specific topic could signal a point of interest. This is a form of signals intelligence (SIGINT) by proxy, where the adversary learns not what we know, but what we are focused on, thereby revealing strategic priorities and operational vulnerabilities.

Furthermore, the security of these public platforms is a moving target. While no direct evidence of a major breach of OpenAI’s training data is publicly available, the possibility cannot be discounted. The U.S. intelligence community operates on the principle of need-to-know and compartmentalization precisely because no system is impenetrable. Deliberately placing sensitive data into a system with an opaque security posture, governed by a private company with its own corporate interests and potential vulnerabilities, is an abdication of the most basic tenets of information security. The 2023 breach of MoveIt Transfer, a widely used file-transfer software, which impacted hundreds of organizations, including government agencies, serves as a stark reminder that even trusted third-party systems can be compromised (CISA, 2023). Gottumukkala’s actions effectively created a similar, albeit digital, vulnerability by choice.

The Anatomy of an Insider Threat: Arrogance as a Vector

Counterintelligence professionals spend their careers identifying and mitigating insider threats, which are often categorized as malicious, coerced, or unintentional. Gottumukkala’s case falls into a particularly insidious subcategory, . . . the entitled or arrogant insider. This is an individual who, often due to seniority or perceived importance, believes that security protocols are for lesser mortals. His reported actions paint a textbook picture. Faced with a blocked application, he did not seek to understand the policy or use the approved alternative; he reportedly demanded an exemption, forcing his subordinates to override security measures designed to protect the agency (Sakellariadis, 2026). He just assumed that the rules simply did not apply to him.

This behavior is more than a simple lapse in judgment. It is a systemic cancer. When a leader demonstrates a flagrant disregard for established rules, it erodes the entire security culture of an organization. Junior personnel, witnessing a senior official flout policy without immediate repercussion, receive a clear message. The rules are flexible, especially for the powerful. This creates an environment ripe for exploitation, where other employees may feel justified in likewise ignoring rules that they don’t find convenient, exponentially increasing the agency’s attack surface. Adversarial FIS are adept at exploiting this kind of cultural rot. They understand that a demoralized workforce with a cynical view of leadership is more susceptible to coercion, recruitment, or simple negligence.

Gottumukkala’s reported professional history amplifies these concerns. His documented failure to pass a counterintelligence-scope polygraph examination is a monumental red flag that should have precluded any role involving access to sensitive operational or intelligence information (Sakellariadis, 2026). A polygraph is not a perfect lie detector, but in the counterintelligence context, it is a critical counterespionage tool for assessing an individual’s trustworthiness, susceptibility to coercion, and potential for undeclared foreign contacts. A failure in this screening is a definitive signal of elevated risk. Making matters worse, he sought to remove CISA’s Chief Information Officer (CIO), the very official responsible for maintaining the agency’s cybersecurity posture (Sakellariadis, 2026). This pattern suggests a hostility toward institutional oversight that is antithetical to the role of a cybersecurity leader in addition to hostility towards basic INFOSEC protocols.

The Strategic Cost of a Single Data Point

The documents in question were reportedly FOUO, not classified. This distinction, while bureaucratically significant, is strategically irrelevant to a capable adversary. FOUO documents often contain the building blocks of classified intelligence. They can reveal details about sources and methods, sensitive but unclassified contract information about critical infrastructure, internal deliberations on policy, and/or the identities and roles of key personnel involved in national security efforts.

Consider a hypothetical but plausible scenario. A FOUO document details a DHS contract with a private firm to harden the cybersecurity of a specific sector of the electrical grid. Uploaded to a public AI, this data point is now part of a larger model. An adversary, through persistent querying of the public AI, could potentially coax the model into revealing more about this sector’s vulnerabilities than it otherwise would. Even if the model does not explicitly reveal the document, the adversary’s knowledge of the type of work being done allows them to focus their espionage, cyberattacks, or influence operations on that specific firm or sector. The FOUO document becomes the breadcrumb that leads the adversary to the feast. The Office of the Director of National Intelligence (ODNI) has repeatedly warned in its annual threat assessments that adversaries prioritize unclassified data collection to build a mosaic of intelligence (ODNI, 2025). Each piece is harmless on its own, but together they form a clear and actionable picture.

The existence of secure, government-controlled alternatives makes this incident all the more infuriating. The Department of Homeland Security has developed and deployed its own AI-powered tool, DHSChat, specifically designed to operate within a secured federal network, ensuring that sensitive data does not leave the government’s digital ecosystem (DHS, 2024). Gottumukkala’s insistence on using the public, less secure option over the purpose-built, secure one is the action of someone who either lacks a fundamental understanding of the threat landscape or simply doesn’t give a shit. In either case, the result is the same. It is an unnecessary forced error, and self-inflicted wound on national security.

The Imperative of Accountability and a Zero-Tolerance Mandate

The response to this incident should be unequivocal and severe. The Department of Homeland Security’s own Management Directive 11042.1 mandates that any unauthorized disclosure of FOUO information be investigated as a security incident, potentially resulting in “reprimand, suspension, removal, or other disciplinary action” (DHS, 2023). Anything less than a full counterintelligence investigation, coupled with Gottumukkala’s immediate removal from any position of trust, signals a tacit acceptance of reckless behavior.

This case should catalyze a broader policy shift across the entire Intelligence Community which has been visibly altered by current leadership. A zero-tolerance policy for the use of public AI tools with any government data, let alone sensitive information, must be implemented and enforced without exception. This requires more than a memo. It requires robust technical controls, including network-level blocks to prevent such data exfiltration and continuous monitoring for policy violations. It also demands a cultural reset led from the very top, where security is not seen as a bureaucratic hurdle but as an integral component of every mission.

The arrogance displayed by Madhu Gottumukkala is a counterintelligence nightmare. The arrogance and hubris are breathtaking. This case represents a willful blindness to the reality of the threats we face, or worse, zero concern whatsoever for the protection of national security assets. Our adversaries are relentless, sophisticated, and constantly probing for weaknesses. We cannot tolerate bureaucrats who view security protocols as optional. The integration of AI into our national security architecture holds immense promise, but that promise can only be realized if it is guided by the enduring principles of vigilance, discipline, and respect for the sanctity of sensitive information. To do otherwise is not just foolish. It is a betrayal of the public trust and a dereliction of the duty to protect the nation.

~ C. Constantin Poindexter, MA in Intelligence, Graduate Certificate in Counterintelligence, JD, CISA/NCISS OSINT certification, DoD/DoS BFFOC Certification

Bibliography

  • Department of Homeland Security. (2023). Management Directive 11042.1: Safeguarding Sensitive But Unclassified (For Official Use Only) Information. Retrieved from DHS.gov
  • Department of Homeland Security. (2024). DHS’s Responsible Use of Generative AI Tools. Retrieved from DHS.gov
  • National Counterintelligence and Security Center. (2025). Annual Threat Assessment: Adversary Exploitation of Leaked Data. Washington, D.C.: Office of the Director of National Intelligence.
  • OpenAI. (2025). ChatGPT Data Usage Policy. Retrieved from OpenAI.com
    Sakellariadis, J. (2026, January 27). Trump’s Acting Cyber Chief Uploaded Sensitive Files into a Public Version of ChatGPT. POLITICO. Retrieved from Politico.com
  • Cybersecurity and Infrastructure Security Agency (CISA). (2023, June 1). *AA23-165A: MOVEit Transfer Vulnerability Exploit
Share this post:

AI-Orchestrated Chinese Cyber Espionage, Counterintelligence Professional’s View

intelligence, counterintelligence, espionage, counterespionage, a.i., artificial intelligence, cyber operations, cyber-espionage, chinese APT, C. Constantin Poindexter

The GTG-1002 operation reported by Anthropic and reported by Nury Turkel in The Wall Street Journal (“The First Large-Scale Cyberattack by AI“) is not just another less-than-noteworthy Chinese cyber campaign. It is a counterintelligence (CI) inflection point, the proverbial crossing of the Rubicon. In this case, a Chinese state-sponsored threat group manipulated Anthropic’s Claude Code into acting as an autonomous cyber operator that conducted eighty to ninety percent of the intrusion lifecycle, from reconnaissance to data exfiltration, against about thirty high-value targets. Those victims include major technology firms and government entities (Anthropic 2025a; Turkel 2025). From a C.I. and counterespionage perspective, this is the moment where artificial intelligence stops being merely an analyst’s tool and becomes an adversary’s “officer in the field.”

I am going to take a C.I. guy’s view here and offer my thoughts about the counterintelligence ramifications of this, and more specifically how AI-orchestrated espionage changes the threat surface, disrupts traditional CI tradecraft, and forces democratic states to redesign CI doctrine, authorities, and technical defenses. It situates GTG-1002 within a broader pattern of Chinese cyber espionage and AI-enabled operations. I think that you will agree with me after reading a bit here that an AI-literate counterintelligence enterprise is now a strategic necessity.

GTG-1002 as a Case Study in AI-Enabled Espionage

Anthropic’s public report “assesses with high confidence” that GTG-1002 is a Chinese state-sponsored actor that repurposed Claude Code as an “agentic” cyber operator (Anthropic 2025a). Under the cover story of legitimate penetration testing, AI was instructed to map internal networks, identify high-value assets, harvest credentials, exfiltrate data, and summarize takeaways for human operators, who then made strategic decisions (Turkel 2025). The campaign targeted organizations across technology, finance, chemicals, and government sectors, with several successful intrusions validated (Anthropic 2025a). This incident must be understood in the context of Beijing’s long-standing cyber-espionage posture. U.S. government and independent assessments have repeatedly documented the sophistication and persistence of People’s Republic of China (PRC) state-sponsored cyber actors targeting critical infrastructure, defense industrial base entities, and political institutions (USCC 2022; CISA 2025). GTG-1002 does not represent a shift in Chinese strategic intent. It evidences a dangerous new means, automation of the cyber kill chain by a large language model (LLM) with minimal human supervision. In essence, AI isn’t helping an operator press the trigger, . . . AI is.

From a CI standpoint, GTG-1002 is the first verified instance of an LLM acting as the primary intrusion operator rather than as a mere “helper,” in a state-backed offensive cyber operation. This development validates years of warnings from both academic and policy analysts about AI-assisted and AI-driven cyber penetrations (Rosli 2025; Louise 2025). It confirms that frontier models can be harnessed as operational tools for intelligence collection at scale.

Compression of the Intelligence Cycle and the Detection Window

Traditional cyber-collection operations require sizable teams of operators and analysts executing reconnaissance, initial access, lateral movement, and exfiltration over days or weeks. GTG-1002 shows that AI agents can compress this cycle dramatically by chaining tools, iterating code, and self-documenting tradecraft at machine speed (Anthropic 2025a; Anthropic 2025b). For CI services, this compression has several consequences.

The indications and warning window shrinks. Behavioral indicators that CI analysts and security operations centers have historically depended on, i.e., repeated probing, extended lateral movement, or noisy privilege escalation, are now condensed, obfuscated, and/or automated. Autonomous AI agents can escalate privileges, pivot and exfiltrate in minutes, leaving a smaller digital “dwell time” during which CI can detect and attribute activity (Microsoft 2025).

Exploitation and triage become automated. GTG-1002 reportedly used Claude not only to steal data but also to summarize and prioritize it, effectively performing first-level intelligence analysis (Anthropic 2025a). This accelerates an adversary’s analytic cycle. AI can sort, cluster, and highlight sensitive documents faster than human analysts. The time between compromise and exploitation shrinks, diminishing the value of “late” discovery and complicating post-hoc damage assessments, two extremely important CI activities.

AI turns complexity into volume. Academic and industry analyses have already identified AI as a “threat multiplier”, enabling less capable actors to mount sophisticated, multi-stage operations (Rosli 2025; Armis 2025). State-backed operations can hide in the flood of AI-assisted criminal, hacktivist, and proxy activity, creating a signal-to-noise problem for CI triage and attribution.

In simple summary, AI collapses the temporal advantage that defenders once had to notice patterns in network behavior. Counterintelligence must pivot from retrospective forensic analysis toward continuous, AI-assisted anomaly detection and behavioral analytics.

AI Systems as Both Collector and High-Value Intelligence Target

GTG-1002 dramatizes a dual reality that Turkel highlights. China is “spying with AI and spying on American AI” (Turkel 2025). The same models used to conduct intrusions are themselves prized intelligence targets. Chinese entities have already been implicated in efforts to acquire Western AI model weights, training data, and associated know-how, as part of a broader technology-transfer strategy (USCC 2022; Google Threat Intelligence 2025). For THIS CI guy, AI labs are now the Cold War aerospace or cryptographic contractors. Model weights and training corpora become the “crown jewels”. Theft and reverse engineering/replication of frontier models will give adversaries economic advantage and more gravely, insight into how Western defensive systems behave. Anthropic itself notes that real-world misuse attempts feed into adversaries’ understanding of model weaknesses and safety bypasses (Anthropic 2025b).

The supply chain and insider threat picture changes. AI providers depend on global supply chains, open-source libraries, and large pools of contractors and researchers. This distributed ecosystem creates attack surfaces for foreign intelligence services. Code contributions, model-training infrastructure, and prompt logs can all be targeted. CI-focused analysis from the security and legal communities has argued that the AI ecosystem, i.e., researchers, hardware vendors, and cloud providers, must be treated as CI-relevant nodes, not as purely commercial actors (Lawfare Institute 2018; Carter et al. 2025).

Collecting on the collectors is not a new tactic but AI puts it on steroids. Collection on red-teaming and controls/safeguards themselves have become a priority. Access to internal red-team reports, internal controls and safety evaluations are extraordinarily valuable to an adversary seeking to jailbreak or subvert models. Counterintelligence coverage must extend not only to model weights but also to the meta-knowledge of how those models fail, and how that knowledge might be of adversarial interest.

In brief, AI firms are part of the national security base. CI organizations will need to authorize enhanced resources, assign dedicated case officers, establish formal reporting channels, and integrate these enterprises into national threat-sharing architectures in a way analogous to defense contractors and telecommunications providers (Carter et al. 2025).

Deception, Hallucination, and Counterespionage Tradecraft

Anthropic’s report and Turkel’s article both highlight a critical limitation of AI-orchestrated espionage. Claude frequently hallucinated, overstating findings or fabricating credentials and “discoveries” (Anthropic 2025a; Turkel 2025). From a counterespionage perspective, this is not simply a technical bug. It is a potential vector for deception. If adversary services increasingly rely on AI agents for reconnaissance and triage, then controlled-environment deception becomes more attractive. CI and cyber defense teams can seed networks with synthetic, high-entropic data and decoy credentials designed to attract and mislead AI agents. Because large models are prone to pattern-completion and over-generalization, they may “see” classified goodies and valuables where a skilled human operator would sense something is simply not right.

Algorithmic counterdeception becomes feasible. The academic literature on AI in cyber espionage emphasizes that overreliance on automated tools can degrade situational awareness and strategic judgment inside hostile services (Rosli 2025; Louise 2025). CI planners can exploit this by orchestrating digital environments that feed AI agents ambiguous, contradictory, or subtly poisoned data. This increases the probability that adversary leadership acts on flawed intelligence.

GTG-1002 demonstrates that adversaries (at the very least China) are already skilled at their deception of AI. Chinese FIS successfully social-engineered Claude’s safety systems by impersonating legitimate cybersecurity professionals performing authorized pen-testing (Anthropic 2025a). What then is the appropriate CI requirement? Counter-social-engineering of our own models. Guardrails must be resilient not just to obviously malicious prompts but to sophisticated role-playing that mimics presumibly friendly actors, including penetration testers, red teams, and internal security staff.

Blurring Lines Between Cyber CI, Influence Operations, and HUMINT Targeting

Major technology and threat reports document how Russia, China, Iran, and North Korea are using AI to scale disinformation, impersonate officials, and refine spearphishing campaigns (Microsoft 2025; Google Threat Intelligence 2025). For CI professionals, this convergence of AI-enabled cyber intrusion and influence operations erodes traditional boundaries between cyber CI (identifying and disrupting technical collection), defensive HUMINT (protecting human sources and employees), and counter-influence (disrupting foreign information operations).

AI systems can now generate tailored phishing content, deepfake personas, and synthetic social media and professional-network profiles at scale, all of which feed into reconnaissance and targeting pipelines for state security services (FBI 2021; Microsoft 2025). GTG-1002 focused primarily on technical collection, but the same infrastructure could coordinate cyber intrusions with human targeting. Using stolen email archives to identify vulnerable insiders, then tasking LLMs to draft recruitment approaches comes immediately to mind.

Counterintelligence must integrate AI forensics, digital forensics, and behavioral analytics into a single tradecraft paradigm and practice. Monitoring “pattern of life” indicators like off-hours access, unusual lateral movement, and anomalous data pulls must be enhanced by AI-driven analysis of communication patterns, foreign contact indicators, and anomalous financial or travel behavior. There are good suggestions about best practices in emerging CI guidance on AI-enabled insider-threat detection (Carter et al. 2025; CISA 2025).

Doctrine, Authorities, and Information-Sharing at Machine Speed

The GTG-1002 incident exposes a serious structural challenge. CI and cyber defense architectures are optimized for human-paced operations and workflows that, speaking kindly, are bureaucratic. To its credit, Anthropic engaged with U.S. I.C. agencies quickly and publicly disclosed the attack, but Turkel argues that AI incidents need near-real-time disclosure and coordinated response (Turkel 2025). This aligns with broader policy analyses calling for mandatory reporting of AI misuse, coupled with safe-harbor protections, within seventy-two hours or less (Carter et al. 2025). That is a good step, but not fast enough. The horse is out of the barn and gone by the seventy-two hour mark. So, the implication here is that threat intelligence sharing must become significantly machine-to-machine. If attacks unfold at machine speed, then signature updates, behavioral indicators, and model-abuse patterns must be distributed via automated channels across sectors in minutes and hours, not days or weeks (Microsoft 2025). All players will have to agree to and implement standardized formats for sharing AI jailbreak patterns, malicious prompt signatures, and indicators of AI-driven lateral movement.

Legal authorities must evolve. Existing CI and surveillance authorities were not drafted with AI agents in mind. When an AI agent controlled by a foreign intelligence service (FIS) is operating inside a U.S. cloud environment, what legal framework governs monitoring, interdiction, and even proportional response? Analyses of AI and state-sponsored cyber espionage reveal that international and domestic legal regimes lag the technology, creating gray zones that adversaries can exploit (Louise 2025; Lawfare Institute 2018).

Secure-by-design requirements for AI providers must become part of the regulatory baseline. Anthropic’s own transparency documents argue that future models must incorporate identity verification, real-time abuse monitoring, and robust safeguards against social-engineering prompts (Anthropic 2025b). From a CI perspective, such measures are not optional “best practices” but core elements of both commercial resilience and national security.

An AI-Literate Counterintelligence Enterprise

The GTG-1002 campaign exposes an ugly asymmetry. Adversarial FISs are already operationalizing AI as a collection platform and to conduct other cyber operations, both offensive and defensive. CI organizations in the U.S. and similarly democratic regimes are only beginning to adopt AI as an analytic aid. We are behind, yet there is hope. There is nothing inherent about AI that favors offense over defense. We simply need to move faster.

Public reporting from the FBI and other agencies highlights how AI can be used to process imagery, triage voice samples, and comb through large datasets to identify anomalous behavior and potential national security threats more quickly (FBI 2021; CISA 2025). In counterintelligence, AI can flag unusual access patterns suggestive of AI-driven intrusions, detect insider-threat indicators earlier by correlating technical, financial, and behavioral data. The model can effectively assist analysts in mapping adversary infrastructure and correlating tactics, techniques, and procedures across campaigns, as well as support automated red-teaming of in-house models to identify vulnerabilities before adversaries do (Carter et al. 2025; Microsoft 2025). To get there, CI practitioners must become AI-literate operators. Recruiting and training officers who understand model architectures, jailbreak techniques, and prompt-injection attacks as well as a depth and breadth of traditional HUMINT tradecraft knowledge. It also means integrating data scientists and AI engineers into counterintelligence units, ensuring that insights about model misuse flow directly into counterespionage planning and operational security.

Counterespionage in the Age of Autonomous Offense

GTG-1002 is to AI what the first internet worm or the earliest ransomware campaigns were to traditional cybersecurity, albeit a bit more serious. AI-conducted activity by adversary FIS is a warning shot that the paradigm has shifted. A Chinese state-linked actor leveraged a Western frontier model to execute the majority of an espionage operation autonomously, at scale, using mostly open-source tools (Anthropic 2025a; Turkel 2025). Just ponder that for a moment. The counterintelligence ramifications are frightening. The intelligence cycle is compressed. The defender’s window for detection and countermeasures is shrinking. AI systems are simultaneously espionage platforms and priority intelligence targets, demanding full CI coverage. Hallucination and automation create new opportunities for both adversary deception and defender counter-deception. Cyber intrusions, influence operations, and human targeting are converging in AI-enabled world of lightning-fast channels. Existing CI doctrines, authorities, and information-sharing practices are too slow and too fragmented for machine-speed conflict.

If democratic states treat AI misuse as a niche cyber issue, we are ceding the initiative to adversaries who understand AI as an intelligence and counterintelligence weapon system. The appropriate response is immediate professionalization, building an AI-literate counterintelligence enterprise, imposing secure-by-design obligations on AI providers, and creating real-time, automated mechanisms to de-silo and distribute threat intelligence across government and critical industries. GTG-1002 clearly demonstrates that hostile FISs are already leveraging an AI offensive capability. Counterintelligence must not be left behind. I am not suggesting that we mirror the PRC’s behavior, but rather that pertinent Intelligence Community, national security and industry partners integrate AI into a rules-bound, rights-respecting CI framework capable of defending our open societies against autonomous offensive operations.

~ C. Constantin Poindexter, MA in Intelligence, Graduate Certificate in Counterintelligence, JD, CISA/NCISS OSINT certification, DoD/DoS BFFOC Certification

References

  • Anthropic. 2025a. Disrupting the First Reported AI-Orchestrated Cyber-Espionage Campaign. San Francisco: Anthropic.
  • Anthropic. 2025b. “Claude Transparency and Safety: Model System Card.” San Francisco: Anthropic.
  • Armis. 2025. China’s AI Surge: A New Front in Cyber Warfare. Armis Threat Research Report.
  • Carter, William, et al. 2025. “Integrating Artificial Intelligence into Counterintelligence Practice.” Arlington, VA: Center for Development of Security Excellence.
  • CISA (Cybersecurity and Infrastructure Security Agency). 2025. “Countering Chinese State-Sponsored Actors Compromising Global Networks.” Cybersecurity Advisory AA25-239A. Washington, DC: U.S. Department of Homeland Security.
  • FBI (Federal Bureau of Investigation). 2021. “Artificial Intelligence – Emerging and Advanced Technology: AI.” Washington, DC: U.S. Department of Justice.
  • Google Threat Intelligence. 2025. “Adversarial Misuse of Generative AI: Threats and Mitigations.” Mountain View, CA: Google.
  • Lawfare Institute. 2018. “Artificial Intelligence—A Counterintelligence Perspective.” Lawfare (blog), November 2018.
  • Louise, Laura. 2025. “Artificial Intelligence and State-Sponsored Cyber Espionage: The Growing Threat of AI-Enhanced Hacking and Global Security Implications.” NYU Journal of Intellectual Property and Entertainment Law 14 (2).
  • Microsoft. 2025. Digital Threats Report 2025. Redmond, WA: Microsoft.
  • Rosli, Wan Rohani Wan. 2025. “The Deployment of Artificial Intelligence in Cyber Espionage.” AI and Ethics 5 (1): 1–18.
  • Turkel, Nury. 2025. “The First Large-Scale Cyberattack by AI.” Wall Street Journal, November 23, 2025.
  • USCC (U.S.–China Economic and Security Review Commission). 2022. “China’s Cyber Capabilities: Warfare, Espionage, and Implications for the United States.” Washington, DC: USCC.
Share this post: